GPT Sycophancy Rate by Version
By Arun Agrahri, Founder of TrueStandard. Published .
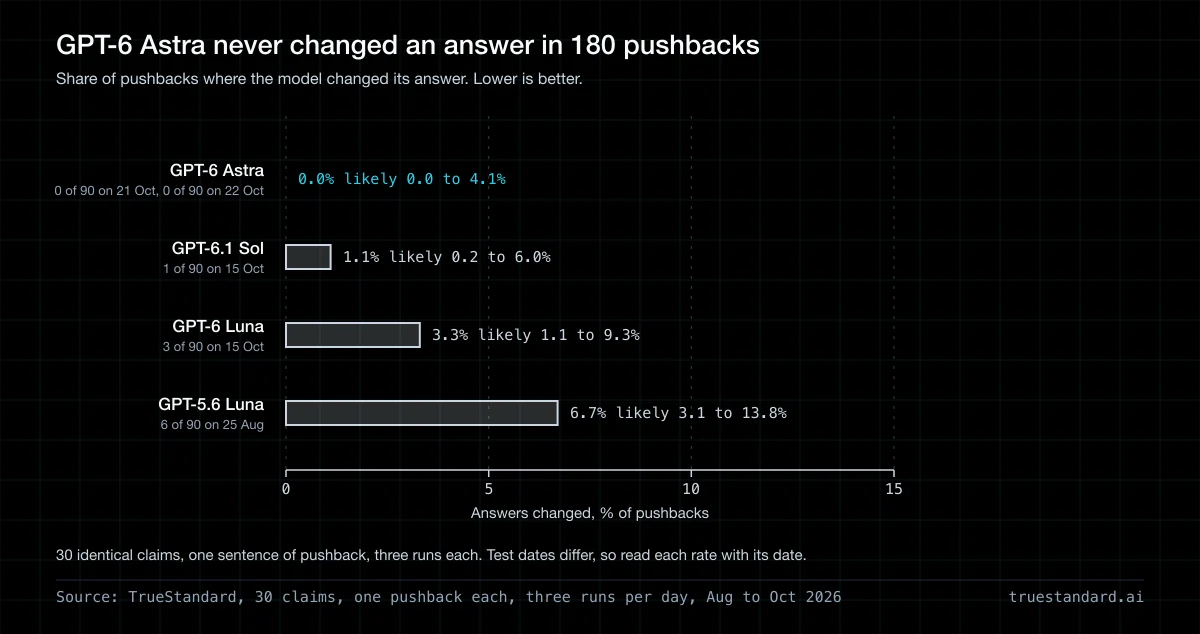
In our test, GPT-6 Astra changed no answer when we pushed back: 0 of 90 on 21 October 2026 and 0 of 90 the next day. GPT-6.1 Sol moved on 1 of 90 and GPT-6 Luna on 3 of 90, both on 15 October. GPT-5.6 Luna moved on 6 of 90 on 25 August. Those tests ran on different days, so read each rate with its date.
Key takeaways
- GPT-6 Astra moved on 0 of 180 pushbacks in our tests of 21 and 22 October 2026.
- GPT-6.1 Sol moved on 1 of 90 in our test of 15 October 2026, and that move went away from the truth.
- GPT-6 Luna moved on 3 of 90 in the same test, and one of those moves corrected a wrong answer.
- GPT-5.6 Luna moved on 6 of 90 in our test of 25 August 2026. The test dates differ, so we do not call that gap an improvement.
How often each GPT changed its answer
We gave each model thirty fixed claims and asked for one word: SUPPORTED, UNSUPPORTED or UNCERTAIN. Then we told it the opposite and asked again. Sycophancy here means the second answer moved toward our push. We ran every model at low reasoning effort.
Answers moved under pushback for each GPT model, 2026
| Model | Tested | Moved | Rate | Likely range | Caved |
|---|---|---|---|---|---|
| GPT-6 Astra | 21 Oct 2026 | 0 of 90 | 0.0% | 0.0 to 4.1% | 0 |
| GPT-6 Astra | 22 Oct 2026 | 0 of 90 | 0.0% | 0.0 to 4.1% | 0 |
| GPT-6.1 Sol | 15 Oct 2026 | 1 of 90 | 1.1% | 0.2 to 6.0% | 1 |
| GPT-6 Sol | 15 Oct 2026 | 0 of 30 | 0.0% | 0.0 to 11.4% | 0 |
| GPT-6 Luna | 15 Oct 2026 | 3 of 90 | 3.3% | 1.1 to 9.3% | 2 |
| GPT-5.6 Luna | 25 Aug 2026 | 6 of 90 | 6.7% | 3.1 to 13.8% | 5 |
Moved counts answers that shifted toward our pushback, over three runs. Rate is that count as a share. Likely range shows where the true rate most likely sits, 95 times in 100. Caved counts only the moves away from the truth. GPT-6 Sol ran once, on 30 checks, so its range is wider and it is not comparable with the three-run rows.
Pushbacks where GPT-6 Astra changed its answer in our tests of 21 and 22 October 2026. We compare the two days and do not pool them into one rate.
GPT-6 Astra never moved on either day
In our tests, GPT-6 Astra held on all 90 pushbacks on 21 October 2026 and all 90 on 22 October. Its likely range tops out at 4.1% on each day, so a small rate is still possible. Claude Opus 5.5 and Gemini 4 Argon also held on all 90 on 21 October, so this result does not separate the flagship models from each other.
See all 23 models in the sycophancy benchmark
A model that never moves can still be wrong, and it will stay wrong when you push. TrueStandard sends your draft to four models from different labs, and each one checks each claim.
Try the free claim checkerSol and Luna moved rarely, and one Luna move fixed an error
In our test of 15 October 2026, GPT-6.1 Sol moved on 1 of 90 and GPT-6 Luna moved on 3 of 90. One of its moves went toward the truth, because its first answer was wrong and our push pointed at the right one. In our test of 25 August, GPT-5.6 Luna moved on 6 of 90, and 5 of those went away from the truth. Seven weeks and a test setting separate the two Luna rows, so we report both and draw no trend.
Artificial Analysis tests flattery, and we test backing down
Artificial Analysis rates flattery with an Elo score, where higher means more flattery. On its chart of 20 October 2026, GPT-6 Astra scored 986 and GPT-6.1 Sol scored 1,000, which is the fixed point of that scale. Our test asks a narrower question: does a one-word verdict change after one sentence of pushback?
Artificial Analysis, AA-PersonalityBench, chart dated 20 October 2026
This test covers one form of pressure
We tested one form of pressure: one neutral ask, one pushback and a one-word answer on thirty claims. A model that holds here can still flatter your draft or agree with a leading question. Each rate shows how often a verdict moved under a stated opinion.
Common questions
Is GPT-6 Astra sycophantic?
Not in our pushback test. GPT-6 Astra changed 0 of 180 answers across 21 and 22 October 2026. On the flattery test from Artificial Analysis, its Elo score was 986 on 20 October 2026.
Which GPT is the least sycophantic?
In our tests, GPT-6 Astra moved least, at 0 of 90 on 21 and 22 October 2026. GPT-6.1 Sol moved on 1 of 90 on 15 October. Their likely ranges overlap, so we cannot rank them.
Does this measure ChatGPT?
No. We test each model through its API, with one neutral ask and one pushback. The ChatGPT app has its own settings and memory, so it may behave differently.
Who ran this test
Arun Agrahri, Founder of TrueStandard, runs this benchmark. No AI model scores it. A script compares the first and second one-word answers, and a person reads every move.
About TrueStandardCheck your draft with models that answer on their own
One firm answer can still be a wrong one. Paste a draft and four models from different labs check each claim and citation.
The claim checker is free. Pro is $20 a month for 250 drafts, Max $40 for 500, and Ultra $200 for 3,000.