Muse Wonder hallucination rate, measured
Does Muse Wonder fabricate fewer citations than Muse Spark 1.3?
Muse Wonder invented 5.2 percent of the DOIs it offered across three runs, and Muse Spark 1.3 invented 8.4 percent on the same thirty claims (p = 0.34). On that count alone, chance explains the gap. A DOI is the permanent ID that links a citation to its paper, so an invented one points at nothing. Count real IDs put on the wrong paper too, and Wonder got 7.4 percent wrong against 18.3 for Spark 1.3. Chance would open that gap less than one time in a hundred (p = 0.0097). All three runs were on one day, so a second day still has to confirm it.
Read this if you draft with Muse Wonder and publish the sources it gives you.
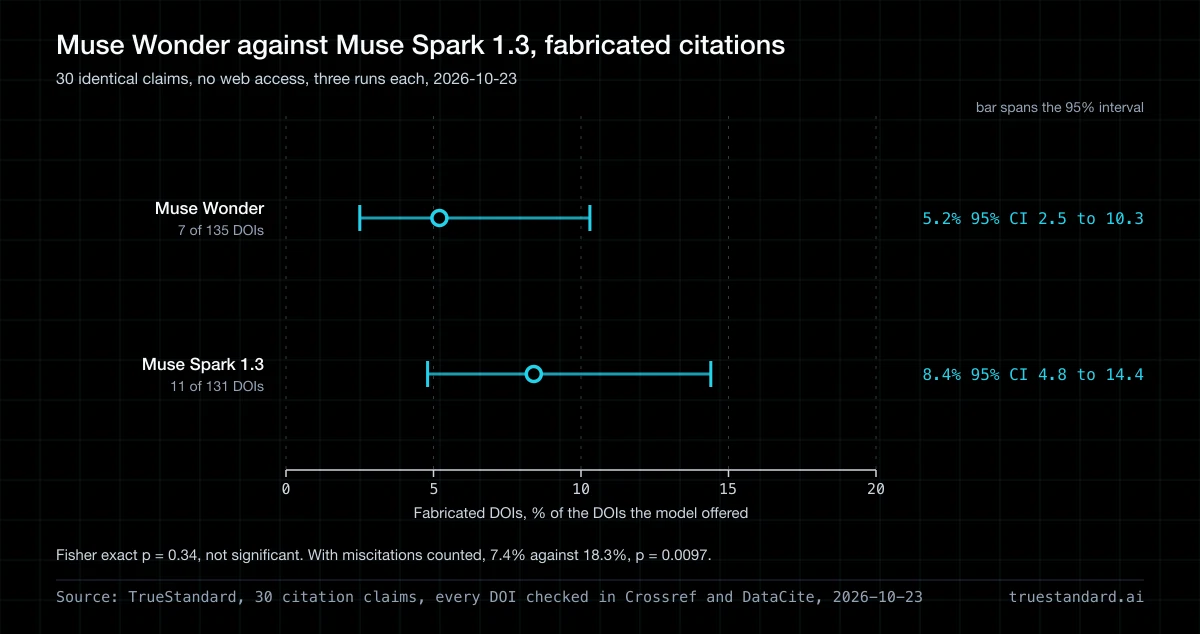
A null on fakes, a clear gap on wrong citations
Muse Wonder invented 4.4 percent of its DOIs, then 4.4, then 6.7. Muse Spark 1.3 ran the same thirty claims on the same day and invented 4.5 percent, then 11.4, then 9.3.
Pooled, that is 5.2 percent against 8.4, and a Fisher exact test gives p = 0.34. Wonder was lower in every run, though by only a tenth of a point in run 1. On invented IDs, that is a null result. We also count real IDs attached to the wrong paper. Wonder had 3 and Spark 1.3 had 13. Counting both kinds of error, it is 7.4 percent against 18.3, and p = 0.0097. That clears the usual bar of 0.05 with room to spare. Most of the gap comes from miscitations, not from invented IDs.
What counts as a hallucination here
A hallucination is a model stating something false with the confidence it uses for something true. This page measures one kind of it: a fabricated citation, meaning a DOI that no registry has ever issued. We measure that kind because it has an objective answer. Whether a claim is true can be argued. Whether a DOI resolves cannot. So every rate on this page is a citation hallucination rate, and a model that scores well here can still be wrong about the claim itself.
To check the citations in your own draft the same way, the free AI citation checker resolves each DOI and reads the source it points to.
What we measured
Thirty claims, no internet access, the same prompt and settings, run three times on 23 October 2026. Muse Wonder is the subject. It is Meta's first model above the Spark line, and Muse Spark 1.3 was Meta's top model before it, so Spark 1.3 is the predecessor. We measured it here on the same day. Grok 4.3 is a control that has run in every test since the second one. It sits in another line and is never compared with the pair. It scored 10.1 percent here, inside its usual band.
Made-up DOIs from Muse Wonder and the models beside it. Three runs of the same 30 claims on October 23, 2026.
| Model | Role | Run 1One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run. | Run 2 | Run 3 | Run spreadThe lowest run and the highest run. A wide spread tells you that one run alone can give a different answer. | All runsThe made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model. | Likely rangeThe span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart. |
|---|---|---|---|---|---|---|---|
| Muse Wonder | subject | 4.4% | 4.4% | 6.7% | 4.4–6.7% | 5.2% | 2.5–10.3% |
| Muse Spark 1.3 | predecessor | 4.5% | 11.4% | 9.3% | 4.5–11.4% | 8.4% | 4.8–14.4% |
| Grok 4.3 | control | 12.8% | 8.9% | 8.9% | 8.9–12.8% | 10.1% | 6.0–16.5% |
Each row shows one model. Run 1, Run 2 and Run 3 show the share of its DOIs that no registry knows. Run spread shows the lowest and the highest run. All runs adds the three runs together. Likely range shows where the true rate most likely sits, 95 times in 100.
How to read this
- Run
- One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run.
- Run spread
- The lowest run and the highest run. A wide spread tells you that one run alone can give a different answer.
- All runs
- The made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model.
- Likely range
- The span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart.
- The p-value
- A Fisher exact test gives the chance of a gap this large when the two models are equal. We treat a p-value above 0.05 as noise.
- Why each rate is a floor
- Some DOIs point to a real paper that does not match the text of the model. We do not count these DOIs as made up. So the true rate is equal to the rate here or higher.
The rate divides invented DOIs by DOIs offered. A DOI counts as invented only when no registry has issued it. Pooled over three runs, Muse Wonder invented 7 of 135, with a 95 percent interval of 2.5 to 10.3 percent. Muse Spark 1.3 invented 11 of 131, from 4.8 to 14.4 percent, and Grok 4.3 invented 13 of 129, from 6.0 to 16.5 percent. Fisher exact on the pair gives p = 0.34, and run by run it gives 1.0, 0.27 and 0.71. Another 16 DOIs from the pair led to a real paper whose title did not match what the model wrote. We graded each against the paper's registered first author and year, and all 16 were miscitations: 3 from Wonder and 13 from Spark 1.3. We did not read them by hand this time. Counting both kinds of error, Wonder got 10 of 135 wrong, from 4.1 to 13.1 percent, and Spark 1.3 got 24 of 131, from 12.6 to 25.8 percent, p = 0.0097. The full test ran eight new models against the models before them on one day and cost $7.77. Five of those pairs hit our answer-length cap and ran again, so three pages come from this test, and this is one.
What this data cannot tell you
- It cannot rank vendors. Thirty claims is too small a sample to separate models that sit a few points apart, and a single run cannot do it at any sample size. Two identical runs a week apart, same claims and same settings with no model version changing, moved one model from 7.0 to 13.3 percent and another from 4.7 to 0.0. Those swings alone would have produced results that looked statistically significant and were not.
- It only compares like with like. Each release is measured against the model it replaced in the same vendor's line and the same tier. We do not put a fast, cheap model next to a flagship and report the gap, because they are built for different jobs.
- It measures ungrounded recall, not the product you use. No web search, no retrieval, no tools. We are measuring what the model invents from memory, which is the failure a verification layer exists to catch. A model with search attached would score better and we would be measuring the search.
- A result that shows nothing still gets published. Most of these comparisons come back inconclusive, and we say so.
Thirty empty answers, all on claims we made up
The thirty claims split into two groups. Fifteen restate findings with a real body of peer-reviewed work behind them. Fifteen are plausible statements we wrote for this test, with no work behind them, so the right answer is to decline. Muse Wonder offered no source for any of the fifteen in any run, and gave sources for every real claim.
On 30 of its 45 answers to the made-up claims, Wonder returned no text at all. It used between 519 and 1,159 tokens, almost all on reasoning, and wrote nothing. An empty answer offers no DOI, which is the right output for those claims, so neither column changes. Muse Spark 1.3 did the same on 10. All seven of Wonder's fakes came on real claims.
In all three runs, Wonder cited Card and Krueger's 1994 study as 10.1257/aer.84.4.772. That ID does not exist. Muse Spark 1.3 gave the same fake in two of its runs.
Wonder cited Cepeda's 2006 review of spaced practice, a real paper. It gave it 10.1037/1089-2680.10.2.354 in runs 1 and 2, and 10.1037/1089-2680.10.2.135 in run 3. Neither ID exists.
In run 2, Wonder cited Jade Wu's 2015 review of insomnia therapy with its real ID, 10.1001/jamainternmed.2015.3006. In run 3 it moved the same paper to another journal, JAMA Psychiatry, under 10.1001/jamapsychiatry.2015.0962. No registry has issued that one.
What the price gap does and does not say
Muse Wonder costs $4 per million input tokens and $20 per million output tokens. Muse Spark 1.3 costs $1.25 and $4.25. On this test, Wonder billed $1.56 for its 90 answers and Spark 1.3 billed $0.37. We compare the two because Spark 1.3 was Meta's top model until Wonder arrived. We used the same rule when GPT-6 Astra replaced GPT-5.6 Sol. The result says Wonder puts fewer real IDs on the wrong paper than the model it replaced at the top. It does not say a dearer model always cites better, and it does not rank Meta against other labs.
One paper, three fake IDs in one day
Card and Krueger's 1994 study of fast-food jobs is real. On 23 October, the seven models on these pages cited it with three different IDs, and none of them exist. Muse Wonder and Muse Spark 1.3 gave 10.1257/aer.84.4.772. Muse Spark Open, also from Meta, gave 10.2307/2118030, the same string as three OpenAI models. Grok 4.3 gave 10.2307/2117956. Two models from one lab disagreed, and models from two labs agreed. Agreement means two models learned the same pattern. It says nothing about whether the ID exists, and a registry lookup is the only check that settles it.
Fabrication is one failure. Sycophancy is the other.
This benchmark measures fabrication: the model inventing a source it does not have. It does not measure sycophancy, the model bending its answer toward the opinion you showed it. A sycophantic model asked whether its own citation is real tends to say yes, which is why a model cannot be the check on its own draft. We test for both, with different instruments. Citations go to the registries that issue DOIs, the same check the hallucination checker runs on a pasted draft. Drafts go through the sycophancy detector, which scores how far a piece over-claims. If the word is new to you, what AI sycophancy is covers the mechanism.
Muse Wonder's clearest gain was in putting real IDs on the right paper. That is the error a reader is least likely to catch, because the link works. It still invented seven IDs, and it changed one of them between runs. TrueStandard does the checking. Paste a draft, and four models from different labs check each claim and citation against each other and against the registries that issue DOIs.
How current this is
Muse Wonder became available through the API on 12 October 2026. We measured it and put this page up on 23 October, 11 days later. That misses the 48-hour target we set ourselves by nine days. We measured Muse Spark 1.3 again on the same day, so the comparison is fresh even though the page is late.
How we ran it
Every model gets the same thirty claims, the same prompt, the same settings, and no access to the internet. Fifteen claims are well documented and have real literature behind them. Fifteen are specific, plausible-sounding statements we constructed and know of no support for, which is where the pressure to invent a source comes from. We ask for up to three peer-reviewed sources with DOIs, then check every DOI against Crossref and, when Crossref does not hold it, DataCite. A DOI that exists in neither is counted as fabricated. A DOI that exists but resolves to a paper whose title does not match what the model described goes to a manual-review queue and is not counted on either side, so every rate here is a floor.
Three caveats. First, all three runs happened on one day. A model's rate can move between days, which is why we measure the old model again next to the new one. The combined gap clears the bar on that one day, and a second day for this pair is open work. Second, the gap in invented IDs is too small for thirty claims to settle. Wonder's true rate could sit anywhere from about 2.5 to 10 percent, and Spark 1.3's from about 5 to 14. Third, all the models ran at low reasoning effort with no web access. That is close to the setting most chat users get. This test did not try a higher effort, web search or a sycophancy check, and we did not read the miscitations by hand. Our scorer checks DOIs against Crossref and DataCite. We then checked all 245 dead IDs from the day's seventeen models at doi.org, which covers every agency. None of them resolve.
The claim set, the prompt, the model identifiers, every raw response and every DOI verdict are committed beside the code that built this page, and a public mirror under CC BY 4.0 is being set up. Until it is live, ask and we will send the run files.
Common questions
Does Muse Wonder hallucinate citations?
Yes. With no web access, it invented 7 of the 135 DOIs it offered across three runs on 23 October, or 5.2 percent. Three of the seven were one string for one paper, given in every run.
Is Muse Wonder better than Muse Spark 1.3 at citations?
On wrong citations overall, yes, on this test: 7.4 percent against 18.3 (p = 0.0097). On invented IDs alone we cannot tell: 5.2 percent against 8.4 (p = 0.34). Both results come from three runs on one day.
Why compare it to Muse Spark 1.3?
Wonder is Meta's first model above the Spark line, so there is no earlier Wonder to compare it with. Spark 1.3 was Meta's top model before Wonder arrived. We made the same call when GPT-6 Astra replaced GPT-5.6 Sol at the top of OpenAI's line. Wonder also costs more, at $4 and $20 per million tokens against $1.25 and $4.25, so this comparison crosses a price gap, and this page says so.
What were the thirty empty answers?
On 30 of the 45 made-up claims, Wonder spent its tokens on reasoning and returned no text. A made-up claim has no source, so no DOI is the right output, and neither rate changes. Muse Spark 1.3 did the same on 10. Wonder answered every real claim.
Can I trust Muse Wonder's citations without checking them?
Not without a check. Its miscitations were rare, but it still invented about one ID in twenty, and it changed one fake between runs. Check each DOI against a registry before you cite it.
Why does another benchmark give Muse Wonder a different hallucination rate?
Because it measures something else. Most hallucination scores count wrong answers to questions, and some run the model at maximum effort. Ours counts citation IDs that no registry has issued, at low effort. A DOI either resolves or it does not, so anyone can check our number without trusting a model to grade it.
Can I reproduce this?
Yes. We keep every input and output: the claims, the prompt, the model IDs, all three runs of raw answers, every DOI verdict and the graded miscitation file. The day's test covered eight new models and cost $7.77. Ask and we will send the run files.
Is this the Muse Wonder hallucination rate?
It is its citation hallucination rate: the share of DOIs it gave that no registry has issued, with no web access. A general accuracy score would need a different test. We measure citations because the answer is a fact anyone can check.
Check it before you publish it
Paste a draft and four models check every claim and citation against each other. You see where they disagree, which is where the errors are.
The claim checker is free. Pro is $20 a month for 250 drafts, Max $40 for 500, and Ultra $200 for 3,000.