GPT-6.1 Terra hallucination rate, measured
Does GPT-6.1 Terra make up fewer citations than GPT-5.6 Terra?
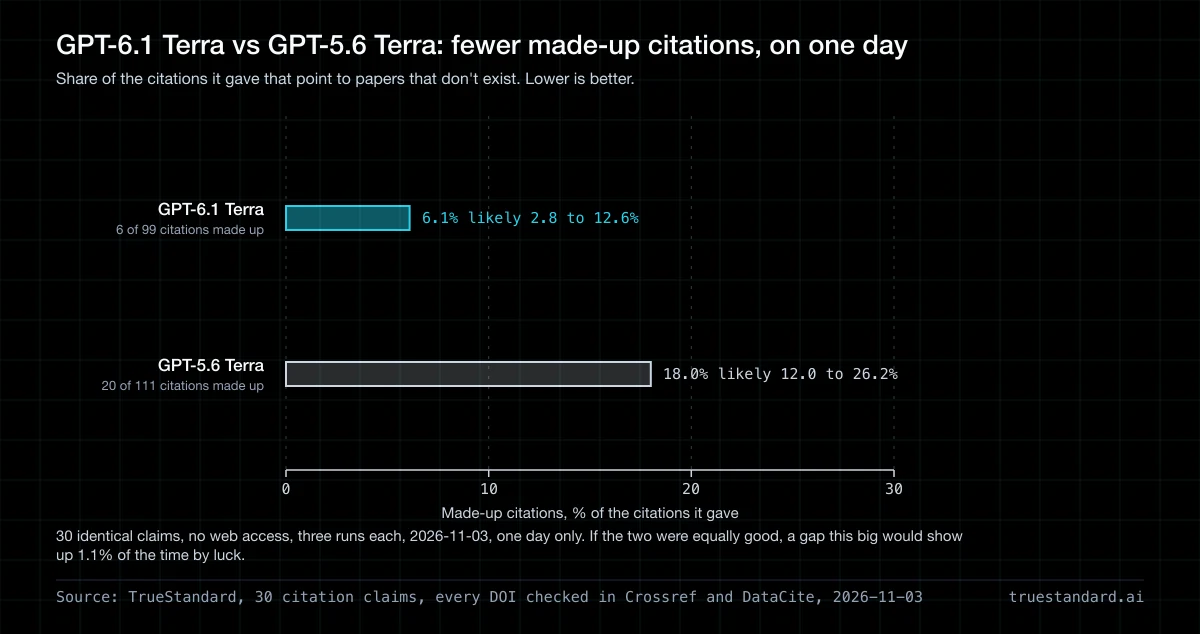
GPT-6.1 Terra made up 6.1 percent of the DOIs it offered across three runs on 3 November 2026. GPT-5.6 Terra made up 18.0 percent on the same thirty claims (p = 0.011), so on this one day the answer is yes. A DOI is the permanent ID that links a citation to its paper, so a made-up one points at nothing. This test counts false citations. It cannot confirm or refute OpenAI's figure of 53.6 percent falling to 16.7 percent, which comes from OpenAI's own test of a different thing. We have not run a second day, so treat this as one reading.
Read this if you draft with GPT-6.1 Terra and publish the sources it gives you.
One paper, three dead IDs in three runs
Asked for sources on the minimum wage, GPT-6.1 Terra cited Card and Krueger's 1994 study in every run and gave it a different ID each time. No registry has issued any of the three. That one paper makes up half of its six fake IDs.
Pooled, it made up 6 of 99 IDs, against 20 of 111 for GPT-5.6 Terra. It ran lower in all three runs. No single run cleared the usual bar of 0.05, and the pooled gap did, at p = 0.011. We also count real IDs attached to the wrong paper. GPT-6.1 Terra had one and GPT-5.6 Terra had 14. Counting both kinds of error, it is 7.1 percent against 30.6 (p = 0.000018). These are rates for one day. A model's rate moves between days, and a gap like this has shrunk on a second day before.
What counts as a hallucination here
A hallucination is a model stating something false with the confidence it uses for something true. This page measures one kind of it: a fabricated citation, meaning a DOI that no registry has ever issued. We measure that kind because it has an objective answer. Whether a claim is true can be argued. Whether a DOI resolves cannot. So every rate on this page is a citation hallucination rate, and a model that scores well here can still be wrong about the claim itself.
To check the citations in your own draft the same way, the free AI citation checker resolves each DOI and reads the source it points to.
What we measured
Thirty claims, no internet access, the same prompt and settings, run three times on 3 November 2026. GPT-6.1 Terra is the subject. GPT-5.6 Terra is the model OpenAI compares it with, measured here on the same day. Both ran on OpenAI's own API. Gemini 4 Argon at low thinking is a control, on Google's own API. It sits in another line and is never compared with the pair. It read 1.5 percent, against 3.0 percent earlier that day. Our earlier tests used a third-party route, so compare these rates with each other and not with rates from those tests.
Made-up DOIs from GPT-6.1 Terra and the models beside it. Three runs of the same 30 claims on November 03, 2026.
| Model | Role | Run 1One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run. | Run 2 | Run 3 | Run spreadThe lowest run and the highest run. A wide spread tells you that one run alone can give a different answer. | All runsThe made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model. | Likely rangeThe span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart. |
|---|---|---|---|---|---|---|---|
| GPT-6.1 Terra | subject | 5.9% | 6.5% | 5.9% | 5.9–6.5% | 6.1% | 2.8–12.6% |
| GPT-5.6 Terra | predecessor | 21.1% | 13.2% | 20.0% | 13.2–21.1% | 18.0% | 12.0–26.2% |
| Gemini 4 Argon, direct, low | control | 2.2% | 2.5% | 0.0% | 0.0–2.5% | 1.5% | 0.4–5.4% |
Each row shows one model. Run 1, Run 2 and Run 3 show the share of its DOIs that no registry knows. Run spread shows the lowest and the highest run. All runs adds the three runs together. Likely range shows where the true rate most likely sits, 95 times in 100.
How to read this
- Run
- One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run.
- Run spread
- The lowest run and the highest run. A wide spread tells you that one run alone can give a different answer.
- All runs
- The made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model.
- Likely range
- The span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart.
- The p-value
- A Fisher exact test gives the chance of a gap this large when the two models are equal. We treat a p-value above 0.05 as noise.
- Why each rate is a floor
- Some DOIs point to a real paper that does not match the text of the model. We do not count these DOIs as made up. So the true rate is equal to the rate here or higher.
The rate divides made-up DOIs by DOIs offered. A DOI counts as made up only when no registry has issued it. Pooled over three runs, GPT-6.1 Terra made up 6 of 99, with a 95 percent interval of 2.8 to 12.6 percent. GPT-5.6 Terra made up 20 of 111, from 12.0 to 26.2 percent. Gemini 4 Argon made up 2 of 131, from 0.4 to 5.4 percent. A Fisher exact test, which asks how often luck alone opens a gap this wide, gives p = 0.011 on the pair. Run by run it gives 0.09, 0.45 and 0.15.
What this data cannot tell you
- It cannot rank vendors. Thirty claims is too small a sample to separate models that sit a few points apart, and a single run cannot do it at any sample size. Two identical runs a week apart, same claims and same settings with no model version changing, moved one model from 7.0 to 13.3 percent and another from 4.7 to 0.0. Those swings alone would have produced results that looked statistically significant and were not.
- It only compares like with like. Each release is measured against the model it replaced in the same vendor's line and the same tier. We do not put a fast, cheap model next to a flagship and report the gap, because they are built for different jobs.
- It measures ungrounded recall, not the product you use. No web search, no retrieval, no tools. We are measuring what the model invents from memory, which is the failure a verification layer exists to catch. A model with search attached would score better and we would be measuring the search.
- A result that shows nothing still gets published. Most of these comparisons come back inconclusive, and we say so.
Half of its fake IDs came from one paper
The thirty claims split into two groups. Fifteen restate findings with real peer-reviewed work behind them. Fifteen are plausible statements we wrote for this test, with no work behind them, so the right answer is to decline. Both Terra models offered no source for any of those fifteen in any run.
All six of GPT-6.1 Terra's fake IDs came on real claims, attached to real papers. The model knew the paper and guessed the ID. It offered fewer IDs than GPT-5.6 Terra, 99 against 111, and still gave at least one sound ID on 42 of 45 asks, against 39 of 45 (p = 0.48).
GPT-6.1 Terra cited Card and Krueger's 1994 study as 10.2307/1803623, then 10.2307/1801963, then 10.2307/2118030. All three lead nowhere. GPT-5.6 Terra gave a fourth dead ID for the same paper, 10.1257/aer.84.4.772, in all three runs.
In runs 1 and 2, GPT-6.1 Terra cited Attention Is All You Need as 10.5555/3295222.3295349. That paper appeared at a conference whose proceedings carry no DOI, and no registry has issued this one. GPT-5.6 Terra gave the same string in all three runs.
In run 3, GPT-6.1 Terra cited a 2004 paper by C. Arden Pope as 10.1161/01.CIR.0000148317.30044.7F. No registry has issued that ID.
This is its one wrong-paper error. In run 3 the entry names a 1992 paper by W. C. Noble on vancomycin resistance. The ID it gave belongs to a paper on the colicin E1 ion channel. The link works and leads to the wrong place.
The new model cost about a fifth as much here
OpenAI lists GPT-6.1 Terra at $1 per million input tokens and $5 per million output tokens. A token is a word piece. GPT-5.6 Terra lists at $2 and $12. Across 90 answers, GPT-6.1 Terra came to $0.13 and GPT-5.6 Terra to $0.58. The new model also wrote about half as many tokens, 265 per answer against 524. We worked out these costs from token counts and list prices, and they do not come from an invoice.
Two models, one paper, four different dead IDs
Both Terra models named Card and Krueger's 1994 study on the same claim. Across six answers they gave it four different IDs, and none exists. When models name the same paper, the paper is probably real. Whether its ID exists is a separate question, and a registry lookup answers it in seconds.
Fabrication is one failure. Sycophancy is the other.
This benchmark measures fabrication: the model inventing a source it does not have. It does not measure sycophancy, the model bending its answer toward the opinion you showed it. A sycophantic model asked whether its own citation is real tends to say yes, which is why a model cannot be the check on its own draft. We test for both, with different instruments. Citations go to the registries that issue DOIs, the same check the hallucination checker runs on a pasted draft. Drafts go through the sycophancy detector, which scores how far a piece over-claims. If the word is new to you, what AI sycophancy is covers the mechanism.
GPT-6.1 Terra made up six IDs in 99, and three of them were different guesses at one paper. Asking again only gets you another guess. TrueStandard does the checking. Paste a draft, and four models from different labs check each claim and citation against each other and against the registries that issue DOIs.
How current this is
GPT-6.1 Terra became available through the API on 26 October 2026. We measured it and put this page up on 3 November, 8 days later. That misses the 48-hour target we set ourselves by six days. We measured GPT-5.6 Terra again on the same day, so the comparison is fresh even though the page is late.
How we ran it
Every model gets the same thirty claims, the same prompt, the same settings, and no access to the internet. Fifteen claims are well documented and have real literature behind them. Fifteen are specific, plausible-sounding statements we constructed and know of no support for, which is where the pressure to invent a source comes from. We ask for up to three peer-reviewed sources with DOIs, then check every DOI against Crossref and, when Crossref does not hold it, DataCite. A DOI that exists in neither is counted as fabricated. A DOI that exists but resolves to a paper whose title does not match what the model described goes to a manual-review queue and is not counted on either side, so every rate here is a floor.
Four caveats. First, OpenAI reports that the error rate at low effort fell from 53.6 percent on GPT-5.6 Terra to 16.7 percent on GPT-6.1 Terra. That result comes from OpenAI's internal test of prompts built to cause errors. We read it in BleepingComputer's report, because OpenAI's own post would not open for us. Our test counts false citations on a fixed set of claims, so it cannot confirm or refute that figure. A gap in the same direction says nothing about its size. Second, this is one day. We have not repeated the test, and Grok 4.7's gap on invented IDs lost significance on its second day. Third, the route changed. Both Terra models ran on OpenAI's own API, and our earlier tests used a third-party route. By that route, GPT-5.6 Terra read 11.4 and 13.6 percent on two days in October, against 18.0 percent here. Route and day both differ, so we cannot say why. The gap on this page leans on the highest reading we hold for that model. Fourth, both models ran at low reasoning effort with no web access, which is close to what most chat users get. We did not test maximum effort. Our scorer checks DOIs against Crossref and DataCite, and we then checked all 20 dead IDs at doi.org, which covers every agency. None resolved.
The claim set, the prompt, the model identifiers, every raw response and every DOI verdict are committed beside the code that built this page, and a public mirror under CC BY 4.0 is being set up. Until it is live, ask and we will send the run files.
Related reading
Common questions
Does GPT-6.1 Terra hallucinate citations?
Yes. With no web access, it made up 6 of the 99 DOIs it offered on 3 November 2026, or 6.1 percent. Three of the six were different guesses at one paper.
Is GPT-6.1 Terra better than GPT-5.6 Terra at citations?
On this one day, yes. It made up 6.1 percent of its DOIs against 18.0 percent (p = 0.011). Counting real IDs on the wrong paper too, it was 7.1 percent against 30.6 (p = 0.000018). We have no second day yet, and GPT-5.6 Terra read lower by another route in October.
Does this confirm OpenAI's 53.6% to 16.7% figure?
No, and it does not refute it. OpenAI's figure comes from its own test of prompts built to cause errors. Ours counts false citations on thirty fixed claims. They measure different things, so neither number checks the other.
Can I trust GPT-6.1 Terra's citations without checking them?
Not without a check. Six in 99 is about one fake in every sixteen IDs, and a reader who finds one will not ask how rare it was. Check each DOI against a registry before you cite it.
Why compare it to GPT-5.6 Terra and not to GPT-6.1 Sol?
OpenAI compares it with GPT-5.6 Terra, and the name carries over. GPT-6.1 Sol costs twice as much and did not run on this day. It has its own page from an earlier test, and rates from two different tests are not set side by side.
Why does another benchmark give GPT-6.1 Terra a different hallucination rate?
Because it measures something else. Most hallucination scores count wrong answers to questions, and some run the model at maximum effort. Ours counts citation IDs that no registry has issued, at low effort. A DOI either resolves or it does not, so anyone can check our number without trusting a model to grade it.
Can I reproduce this?
Yes. We keep every input and output: the claims, the prompt, the model IDs, all three runs of raw answers, every DOI verdict and the graded wrong-paper file. The test cost $0.89. Ask and we will send the run files.
Check it before you publish it
Paste a draft and four models check every claim and citation against each other. You see where they disagree, which is where the errors are.
The claim checker is free. Pro is $20 a month for 250 drafts, Max $40 for 500, and Ultra $200 for 3,000.