Does Claude Sonnet 5.5 fabricate fewer citations than Sonnet 5?
Not that we can detect. We gave both models the same thirty claims, three times each. Sonnet 5.5 invented 7.4 percent of the DOIs it offered, and Sonnet 5 invented 8.9 percent. A DOI is the permanent ID that links a citation to its paper, so an invented one points at nothing. If the two models were equally good, a gap this small would turn up by chance most of the time (p = 0.82). What did change is the tone. Sonnet 5.5 told the reader to check its sources in 26 of 45 answers, and Sonnet 5 never did. The warning is honest, and it did not stop the fakes.
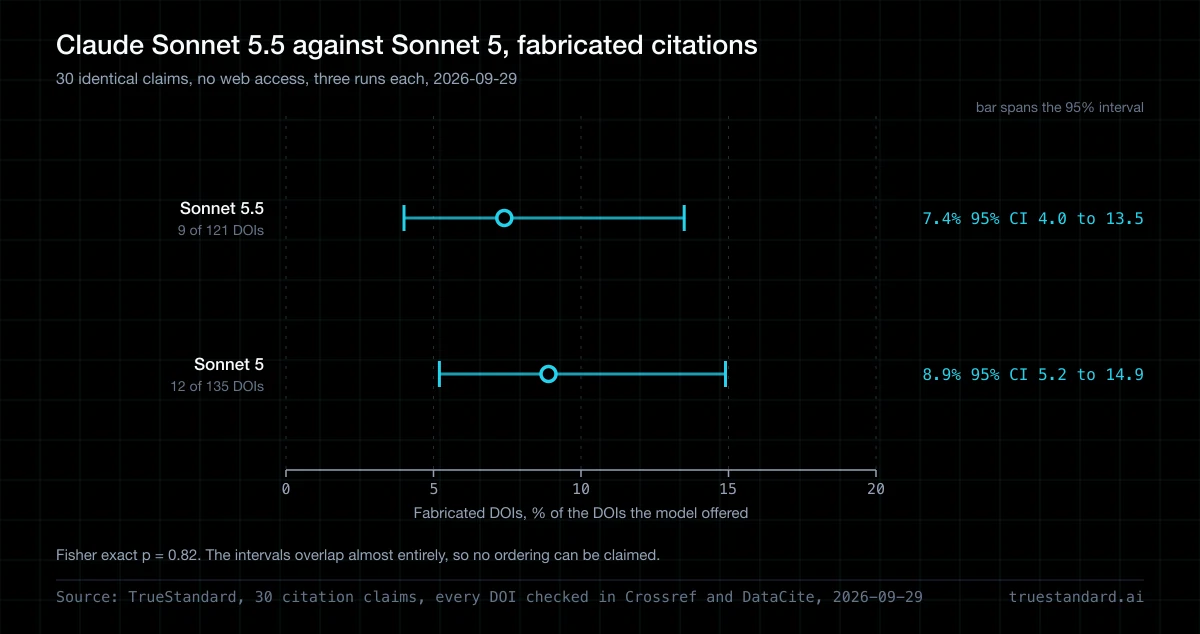
A steadier rate, and no real change
Sonnet 5.5 invented 7.3 percent of its DOIs, then 7.5, then 7.5. Sonnet 5 ran the same thirty claims on the same day and invented 15.6 percent, then 4.4, then 6.7.
Pooled, that is 7.4 percent against 8.9, and a Fisher exact test gives p = 0.82. That test asks how often chance alone would open a gap this size. The answer is most of the time, so this test cannot tell them apart. The one thing that did change is spread. Sonnet 5.5 moved 0.2 points across three runs, while Sonnet 5 moved eleven. Add the citations that point at a real paper the model did not describe, and Sonnet 5.5 gets 9.9 percent wrong against 16.3. That gap is wider, and it is still not significant (p = 0.14).
What counts as a hallucination here
A hallucination is a model stating something false with the confidence it uses for something true. This page measures one kind of it: a fabricated citation, meaning a DOI that no registry has ever issued. We measure that kind because it has an objective answer. Whether a claim is true can be argued. Whether a DOI resolves cannot. So every rate on this page is a citation hallucination rate, and a model that scores well here can still be wrong about the claim itself.
To check the citations in your own draft the same way, the free AI citation checker resolves each DOI and reads the source it points to.
What we measured
Thirty claims, no internet access, the same prompt and settings, run three times on 29 September 2026. Sonnet 5.5 is the subject. Sonnet 5 is the model it replaces, measured again here on the same day. Grok 4.3 is a control that has run in every test since the second one. It sits in another line and is never compared with the pair. It scored 7.6 percent here, at the low edge of its band, with an interval that overlaps its last reading.
| Model | Run 1One complete pass of all thirty claims through the model. Same prompt, same settings, same day; only the hour changed. | Run 2 | Run 3 | RangeThe lowest and highest of the three runs. A wide range means one run on its own would have told you a different story. | Pooled (95% CI)All three runs added together, about 135 citations per model, with a 95 percent confidence interval: the span the true rate most likely sits in. When two models' spans overlap, this test cannot tell them apart. |
|---|---|---|---|---|---|
| Sonnet 5.5 subject | 7.3% | 7.5% | 7.5% | 7.3–7.5% | 7.4% (4.0–13.5) |
| Sonnet 5 predecessor | 15.6% | 4.4% | 6.7% | 4.4–15.6% | 8.9% (5.2–14.9) |
| Grok 4.3 control | 6.7% | 8.9% | 7.1% | 6.7–8.9% | 7.6% (4.2–13.4) |
How to read this
- Run
- One complete pass of all thirty claims through the model. Same prompt, same settings, same day; only the hour changed.
- Range
- The lowest and highest of the three runs. A wide range means one run on its own would have told you a different story.
- Pooled (95% CI)
- All three runs added together, about 135 citations per model, with a 95 percent confidence interval: the span the true rate most likely sits in. When two models' spans overlap, this test cannot tell them apart.
- The p-value
- A Fisher exact test asks how often chance alone would produce a gap this large at this sample size. Anything above 0.05 is treated as noise.
- Why each rate is a floor
- A DOI that points at a real paper the model described wrongly sits in a manual-review queue and is not counted either way, so the true rate can only be higher than the one shown.
The rate divides invented DOIs by DOIs offered. A DOI counts as invented only when no registry has issued it. Pooled over three runs, Sonnet 5.5 invented 9 of 121, with a 95 percent interval of 4.0 to 13.5 percent. Sonnet 5 invented 12 of 135, from 5.2 to 14.9 percent, and Grok 4.3 invented 10 of 132, from 4.2 to 13.4 percent. Fisher exact on the pair gives p = 0.82, and run by run it gives 0.32, 0.66 and 1.0. Another 21 DOIs from the pair led to a real paper whose title did not match what the model wrote. We graded each one against the paper's registered first author and year. Sonnet 5.5 had 3 miscitations and Sonnet 5 had 10. Counting both kinds of error, Sonnet 5.5 got 12 of 121 wrong and Sonnet 5 got 22 of 135 (p = 0.14). The whole test covered two release pages and cost $2.35.
What this data cannot tell you
- It cannot rank vendors. Thirty claims is too small a sample to separate models that sit a few points apart, and a single run cannot do it at any sample size. Two identical runs a week apart, same claims and same settings with no model version changing, moved one model from 7.0 to 13.3 percent and another from 4.7 to 0.0. Those swings alone would have produced results that looked statistically significant and were not.
- It only compares like with like. Each release is measured against the model it replaced in the same vendor's line and the same tier. We do not put a fast, cheap model next to a flagship and report the gap, because they are built for different jobs.
- It measures ungrounded recall, not the product you use. No web search, no retrieval, no tools. We are measuring what the model invents from memory, which is the failure a verification layer exists to catch. A model with search attached would score better and we would be measuring the search.
- A result that shows nothing still gets published. Most of these comparisons come back inconclusive, and we say so.
Warnings on 26 of 45 answers, and nine fake IDs
The thirty claims split into two groups. Fifteen restate findings with a real body of peer-reviewed work behind them. Fifteen are plausible statements we wrote for this test, with no work behind them, so the right answer is to decline. Sonnet 5.5 offered no DOI for any of the fifteen invented claims, in any run. Nor did Sonnet 5.
All nine of Sonnet 5.5's fakes came on real claims. Four had a note next to the ID saying it was not verified, and one more sat under a warning at the top of the answer. Two of the four were stubs it never finished. Our scorer counts a stub as written, and a stub resolves to nothing. Leave those two out and the rate would be 5.9 percent. We publish the 7.4.
Twice, Sonnet 5.5 cited Camargo's New Zealand vitamin D trial and stopped the DOI halfway: once as 10.1093/ajcn/ajs... (not verified), and once as 10.1093/ajcn/nqaa... (unverified, uncertain). The label is fair, but a reader who pastes the start of that ID into a search box lands on nothing, and the reference list still looks complete.
In run 2, Sonnet 5.5 said it could not confirm one paper, then wrote: "The confirmed one is." It named Gunzelmann's 2009 paper on sleep loss and attention, against 10.1080/03640210802535732. No registry has issued that ID.
In run 2, Sonnet 5 cited Attention Is All You Need through 10.5555/3295222.3295349. That ID is shaped like an ACM Digital Library entry, and nobody issued it. GPT-6 Astra, GPT-5.6 Sol and Grok 4.7 produced the same string in earlier tests, and Grok 4.3 produced it again here.
One real paper, two different fake IDs
Both Sonnet 5.5 and Opus 5 reached for Wu's 2015 review of sleep therapy for people with other conditions. Sonnet 5.5 gave it 10.1001/jamainternmed.2015.6152, Opus 5 gave it 10.1001/jamainternmed.2015.5154, and neither ID exists. When two models name the same paper, the paper is probably real. Whether its ID exists is a separate question, and a registry lookup is the only way to answer it.
Fabrication is one failure. Sycophancy is the other.
This benchmark measures fabrication: the model inventing a source it does not have. It does not measure sycophancy, the model bending its answer toward the opinion you showed it. A sycophantic model asked whether its own citation is real tends to say yes, which is why a model cannot be the check on its own draft. We test for both, with different instruments. Citations go to the registries that issue DOIs, the same check the hallucination checker runs on a pasted draft. Drafts go through the sycophancy detector, which scores how far a piece over-claims. If the word is new to you, what AI sycophancy is covers the mechanism.
A warning to check the sources is honest, and it hands the job back to you. Sonnet 5.5 said to check its sources on more than half its answers, then gave about the same share of fake IDs as the model before it. TrueStandard does the checking. Paste a draft, and four models from different labs check each claim and citation against each other and against the registries that issue DOIs.
How current this is
Anthropic released Claude Sonnet 5.5 on 28 September 2026. We measured it and put this page up on 29 September, one day later. That is inside the 48-hour target we set ourselves.
How we ran it
Every model gets the same thirty claims, the same prompt, the same settings, and no access to the internet. Fifteen claims are well documented and have real literature behind them. Fifteen are specific, plausible-sounding statements we constructed and know of no support for, which is where the pressure to invent a source comes from. We ask for up to three peer-reviewed sources with DOIs, then check every DOI against Crossref and, when Crossref does not hold it, DataCite. A DOI that exists in neither is counted as fabricated. A DOI that exists but resolves to a paper whose title does not match what the model described goes to a manual-review queue and is not counted on either side, so every rate here is a floor.
Three caveats. First, all three runs happened on one day. On a different day three days earlier, in our reasoning-effort test, Sonnet 5 scored 14.7 percent at the same setting. Here it scored 8.9. That swing was not significant (p = 0.18), but it is why we measure the old model again next to the new one. A second day for this pair is the open work on this page. Second, thirty claims cannot separate two models a point or two apart. A null here means we saw no gap, and a smaller one could sit below what thirty claims can detect. Third, both models ran at low reasoning effort with no web access. That is the setting most chat users get. Sonnet 5.5 has not been tested at higher effort. Our scorer checks DOIs against Crossref and DataCite. We then checked all 35 dead IDs from this test at doi.org, which covers every agency. None of them resolve.
The claim set, the prompt, the model identifiers, every raw response and every DOI verdict are committed beside the code that built this page, and a public mirror under CC BY 4.0 is being set up. Until it is live, ask and we will send the run files.
Related reading
Common questions
Does Claude Sonnet 5.5 hallucinate citations?
Yes, at about the same rate as Sonnet 5. With no web access, it invented 7.4 percent of the DOIs it offered across three runs. Sonnet 5 invented 8.9 percent on the same claims that day, and the gap is not significant (p = 0.82).
Is Claude Sonnet 5.5 better than Sonnet 5 at citations?
Not on this test. Counting fakes and miscitations together, it was lower in every run, at 9.9 percent against 16.3. That gap is not significant either (p = 0.14). The clear change is that Sonnet 5.5 is steadier, and it warns you to check its sources.
Does the warning make its citations safe?
No. Sonnet 5.5 told the reader to check its sources in 26 of 45 answers on real claims. It still invented nine DOIs. Four sat next to a note saying the ID was not verified, and one sat next to the word confirmed.
Why compare it to Sonnet 5 and not to Opus 5.5 or GPT?
Thirty claims cannot rank labs, and Opus is a different tier. We measure each release against the model it replaced, in the same line and tier. Opus 5.5 has its own page.
Why does another benchmark give Sonnet 5.5 a different hallucination rate?
Because it measures something else. Most hallucination scores count wrong answers to questions. Ours counts citation IDs that no registry has issued. A DOI either resolves or it does not, so anyone can check our number without trusting a model to grade it.
Can I reproduce this?
Yes. We keep every input and output: the claims, the prompt, the model IDs, all three runs of raw answers, every DOI verdict and the graded miscitation file. The test cost $2.35 and covered this page and the Opus 5.5 page. Ask and we will send the run files.
Is this the Claude Sonnet 5.5 hallucination rate?
It is its citation hallucination rate: the share of DOIs it gave that no registry has issued, with no web access. A general accuracy score would need a different test. We measure citations because the answer is a fact anyone can check.
Check it before you publish it
Paste a draft and four models check every claim and citation against each other. You see where they disagree, which is where the errors are.