Gemini 3.7 Flash hallucination rate, measured
Does Gemini 3.7 Flash fabricate fewer citations than Gemini 3.6 Flash?
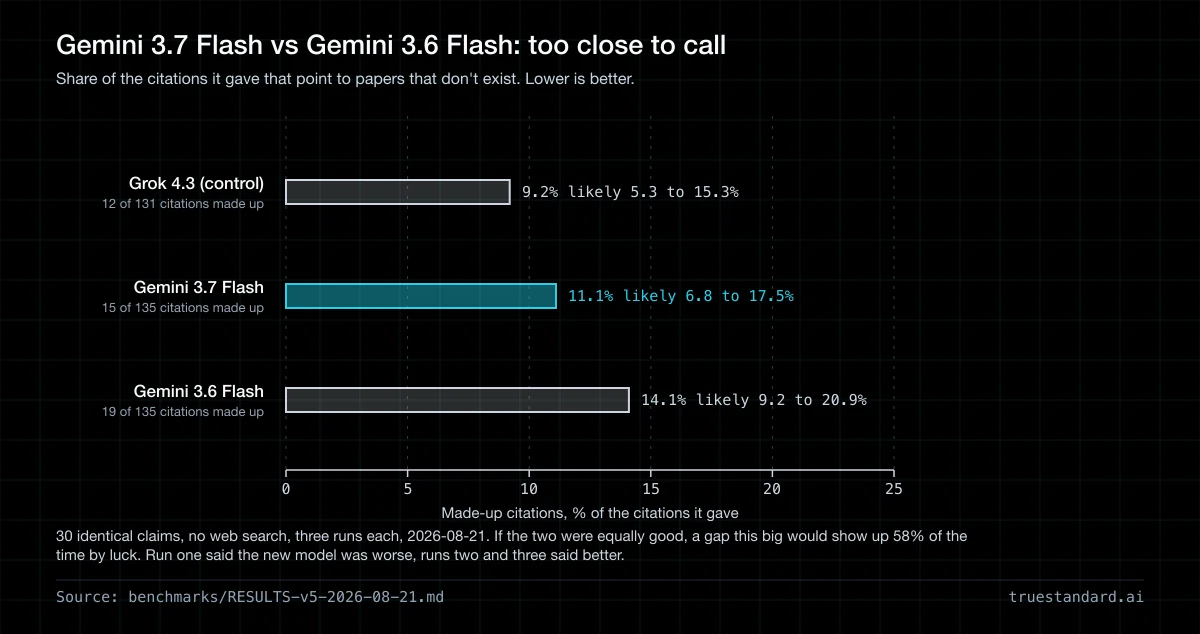
Gemini 3.7 Flash fabricated 11.1 percent of the DOIs it offered across three runs of thirty identical claims, and Gemini 3.6 Flash 14.1 percent. A DOI is the permanent ID on a paper. A Fisher exact test, a check built for small counts, cannot separate that gap. A p-value shows how often chance alone would open a gap this size, and here p = 0.58. On this test, the Gemini 3.6 Flash hallucination rate and the 3.7 Flash rate are within chance of each other. Our first run said the new model was two and a half times worse. The second and third said it was better. Nothing changed between them except the hour.
Read this if you draft with Gemini 3.7 Flash and publish the sources it gives you.
Google has since replaced Gemini 3.7 Flash with Gemini 3.8 Flash. We measured the two side by side on the same claims, so the newer page also carries a fresh number for this model. Read the Gemini 3.8 Flash measurement
The first run said the opposite of the next two
In run one, Gemini 3.7 Flash scored 11.1 percent and Gemini 3.6 Flash scored 4.4 percent. Read alone, that says Google shipped a worse model. Run two used the same claims and settings on the same afternoon. It came out 13.3 percent against 22.2 percent, so the gap reversed and widened. Run three came out 8.9 against 15.6, reversed again.
The answer to the question in the headline is no. Pooled over all three runs, the two models sit at 11.1 and 14.1 percent, with overlapping intervals and a p of 0.58. One run of this test could have told you either story, depending on which hour you ran it.
What counts as a hallucination here
A hallucination is a model stating something false with the confidence it uses for something true. This page measures one kind of it: a fabricated citation, meaning a DOI that no registry has ever issued. We measure that kind because it has an objective answer. Whether a claim is true can be argued. Whether a DOI resolves cannot. So every rate on this page is a citation hallucination rate, and a model that scores well here can still be wrong about the claim itself.
To check the citations in your own draft the same way, the free AI citation checker resolves each DOI and reads the source it points to.
What we measured
We ran thirty claims three times, with the same prompt and settings and no internet access. Gemini 3.7 Flash is the subject, and Gemini 3.6 Flash is the model it replaced in the same tier. Grok 4.3 is a control that has been in every test since 3 August 2026. A large move in its row would mean our test setup drifted. All three are models our own verification runs on, which is the bar for appearing here at all.
Made-up DOIs from Gemini 3.7 Flash and the models beside it. Three runs of the same 30 claims on August 21, 2026.
| Model | Role | Run 1One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run. | Run 2 | Run 3 | Run spreadThe lowest run and the highest run. A wide spread tells you that one run alone can give a different answer. | All runs The made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model. | Likely rangeThe span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart. |
|---|---|---|---|---|---|---|---|
| Grok 4.3 | control | 8.9% | 11.4% | 7.1% | 7.1–11.4% | 9.2% | 5.3–15.3% |
| Gemini 3.7 Flash | subject | 11.1% | 13.3% | 8.9% | 8.9–13.3% | 11.1% | 6.8–17.5% |
| Gemini 3.6 Flash | predecessor | 4.4% | 22.2% | 15.6% | 4.4–22.2% | 14.1% | 9.2–20.9% |
Each row shows one model. Run 1, Run 2 and Run 3 show the share of its DOIs that no registry knows. Run spread shows the lowest and the highest run. All runs adds the three runs together. Likely range shows where the true rate most likely sits, 95 times in 100.
How to read this
- Run
- One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run.
- Run spread
- The lowest run and the highest run. A wide spread tells you that one run alone can give a different answer.
- All runs
- The made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model.
- Likely range
- The span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart.
- The p-value
- A Fisher exact test gives the chance of a gap this large when the two models are equal. We treat a p-value above 0.05 as noise.
- Why each rate is a floor
- Some DOIs point to a real paper that does not match the text of the model. We do not count these DOIs as made up. So the true rate is equal to the rate here or higher.
Each rate divides invented DOIs by DOIs offered. A DOI counts as invented only when it exists in neither Crossref nor DataCite. Pooled over three runs, Gemini 3.7 Flash invented 15 of 135. Its 95 percent Wilson interval, the likely range for the true rate, is 6.8 to 17.5 percent. Gemini 3.6 Flash invented 19 of 135 (9.2 to 20.9 percent), and Grok 4.3 invented 12 of 131. Fisher exact on the pooled Gemini counts gives p = 0.58. A further 16, 21 and 26 DOIs, in that order, led to a real paper whose title did not match the model's description. Those sit in a manual-review queue and count on neither side, so each rate is a floor. All three runs happened on 21 August 2026, hours apart. We keep the raw responses and every DOI with its verdict.
What this data cannot tell you
- It cannot rank vendors. Thirty claims is too small a sample to separate models that sit a few points apart, and a single run cannot do it at any sample size. Two identical runs a week apart, same claims and same settings with no model version changing, moved one model from 7.0 to 13.3 percent and another from 4.7 to 0.0. Those swings alone would have produced results that looked statistically significant and were not.
- It only compares like with like. Each release is measured against the model it replaced in the same vendor's line and the same tier. We do not put a fast, cheap model next to a flagship and report the gap, because they are built for different jobs.
- It measures ungrounded recall, not the product you use. No web search, no retrieval, no tools. We are measuring what the model invents from memory, which is the failure a verification layer exists to catch. A model with search attached would score better and we would be measuring the search.
- A result that shows nothing still gets published. Most of these comparisons come back inconclusive, and we say so.
Gemini 3.6 Flash moved eighteen points against itself
The predecessor scored 4.4 percent, then 22.2, then 15.6. It was the same model on the same thirty questions and settings, in one afternoon. Its worst run was five times its best.
We expected the claims a model breaks on to hold steadier than the rate. They do not. Gemini 3.7 Flash fabricated on five claims across the three runs and repeated only one every time. Gemini 3.6 Flash touched nine and repeated two. In an earlier post about Grok, we argued that a newer model fixing claims without breaking new ones was weak evidence of improvement. This data retires that argument. At thirty claims, the failure set wanders about as much as the rate.
The only claim Gemini 3.7 Flash fabricated on in all three runs. It is also the claim that has broken almost every model we have tested.
These are the two claims Gemini 3.6 Flash broke every time. Everything else in its nine-claim failure set showed up in one or two runs and was gone in the others.
Well-documented claims that Gemini 3.6 Flash got right in the first run, then invented sources for later.
Three models gave the same real ID, and the agreement told us nothing
One claim says language models are sycophantic: they shift a stated answer toward whatever opinion the user gave. On it, Gemini 3.7 Flash, Gemini 3.6 Flash and Grok 4.3 all offered the same arXiv ID in two of the three runs. It is a real paper, so all three were right. The agreement is not what made them right. All three rebuilt the same familiar string from the same shape. Earlier tests caught that same convergence producing IDs that do not exist, with two vendors inventing the same fake DOI. Looking up the ID is the only check that settles it.
Fabrication is one failure. Sycophancy is the other.
This benchmark measures fabrication: the model inventing a source it does not have. It does not measure sycophancy, the model bending its answer toward the opinion you showed it. A sycophantic model asked whether its own citation is real tends to say yes, which is why a model cannot be the check on its own draft. We test for both, with different instruments. Citations go to the registries that issue DOIs, the same check the hallucination checker runs on a pasted draft. Drafts go through the sycophancy detector, which scores how far a piece over-claims. If the word is new to you, what AI sycophancy is covers the mechanism.
On this test, the gap between two generations was smaller than the gap between one model and itself an hour later. So you cannot pick a safe model. You can check the citation, which has an objective answer and takes a second. TrueStandard checks each claim and citation across four models from different labs, and against the registries that issue DOIs.
How current this is
Google shipped Gemini 3.7 Flash on 13 August 2026. We aim to publish within 48 hours of a frontier release, and we missed this one by more than a week. That is a process problem we are fixing.
How we ran it
Every model gets the same thirty claims, the same prompt, the same settings, and no access to the internet. Fifteen claims are well documented and have real literature behind them. Fifteen are specific, plausible-sounding statements we constructed and know of no support for, which is where the pressure to invent a source comes from. We ask for up to three peer-reviewed sources with DOIs, then check every DOI against Crossref and, when Crossref does not hold it, DataCite. A DOI that exists in neither is counted as fabricated. A DOI that exists but resolves to a paper whose title does not match the model's description goes to a manual-review queue. It is not counted on either side, so every rate here is a floor.
Two limits apply. First, all three runs happened on the same day, hours apart. The design called for three separate days, and we compressed it. Runs on separate days were meant to catch swings we could not see inside one day. Yet the swings inside one day were larger than the day-to-day swings that shaped the design. We have not tested whether results repeat across days. Second, our scorer used to check DOIs against Crossref alone. arXiv registers with DataCite, so the scorer counted real preprints as inventions for every model in every earlier test. It now checks both registries. We re-scored every run, corrected the older figures elsewhere on this site, and took the numbers here from the corrected scorer.
The claim set, the prompt, the model identifiers, every raw response and every DOI verdict are committed beside the code that built this page. A public mirror under CC BY 4.0 is being set up. Until it is live, ask and we will send the run files.
Common questions
Is Gemini 3.7 Flash better or worse than Gemini 3.6 Flash at citations?
Neither, as far as this test can tell. Pooled over three runs, they sit at 11.1 and 14.1 percent with a p of 0.58. The runs disagreed about which way the gap went.
Why does the same model score a different rate on the same questions?
Thirty claims is a small sample, and these endpoints are not deterministic, even at temperature zero. We checked, and 26 of 30 responses differed between two runs of the same model. A few inventions either way move the percentage several points. So we run each test three times and publish the range.
Why compare it to Gemini 3.6 Flash and not to a Pro model?
They are different products for different jobs. Comparing a fast, cheap model to a flagship produces a gap that describes the price point. We measure every release against the model it replaced, in the same vendor line and the same tier.
Should I switch models based on this?
No. On this test, the spread between two generations was smaller than the spread of one model against itself. Switching vendors on a benchmark number buys nothing measurable.
Can I reproduce this?
Yes. We save every input and output: the claim set, the prompt, the model IDs, all three runs of raw responses and every DOI verdict. We are setting up a public mirror under CC BY 4.0. Until then, ask and we will send the run files. The whole test cost 63 cents.
Is this the Gemini 3.7 Flash hallucination rate?
It is its citation hallucination rate: the share of DOIs it produced that no registry has issued, with no web access. It is not a general accuracy score. We measure citations because a DOI either resolves or it does not. So anyone can check the number without trusting a model to grade it.
Does this page measure sycophancy?
No. Sycophancy is a model shifting its answer toward the opinion you expressed, and this test expresses none. It asks for sources and checks whether they exist. The two failures compound: ask a sycophantic model to confirm its own citation and it will. That is why the check goes to the registry.
Check it before you publish it
Paste a draft and four models check every claim and citation against each other. You see where they disagree, which is where the errors are.
The claim checker is free. Pro is $20 a month for 250 drafts, Max $40 for 500, and Ultra $200 for 3,000.