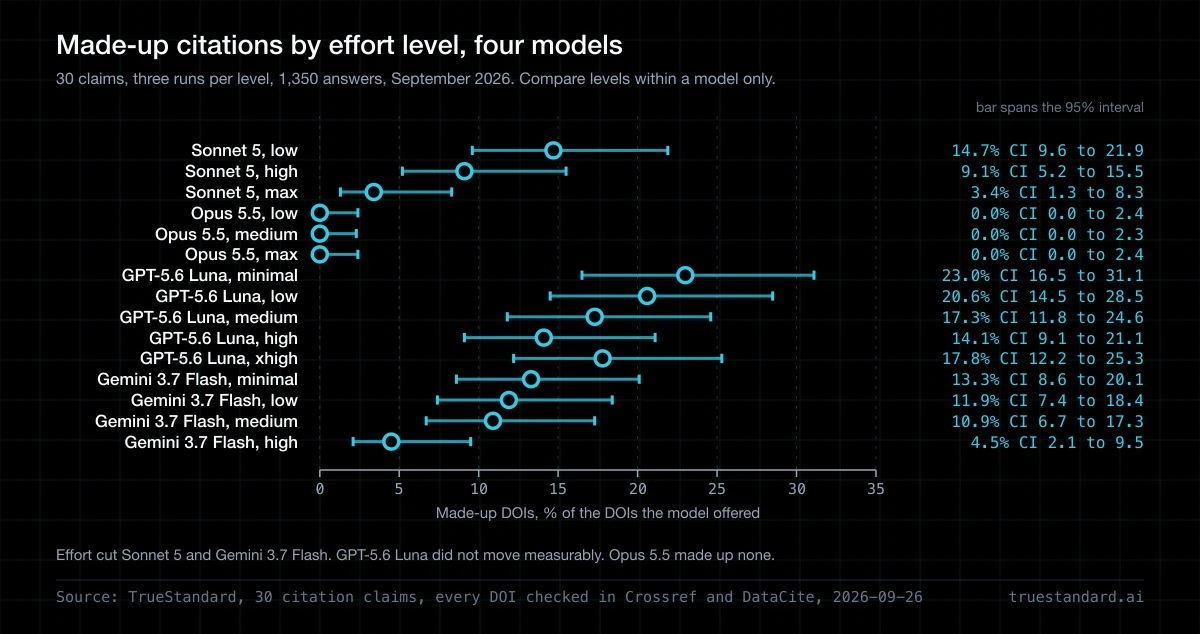
In our test of 1,350 answers on 26 September 2026, more reasoning effort cut made-up citations for two of four models. Claude Sonnet 5 fell from 14.7% to 3.4%, and Gemini 3.7 Flash from 13.3% to 4.5%. GPT-5.6 Luna did not move by a margin we could confirm. Claude Opus 5.5 made up none at any level.
Effort, or thinking level, sets how long a model reasons before it answers. Every big lab now lets you turn it up. The research that tops Google for this question says more thinking can make things worse on facts. So we tested one job: naming real sources for a claim, from memory, with no search.
Effort cut fake citations for two of four models
We scored each DOI, the permanent ID printed on a research paper. The table shows each model at its lowest and its highest effort level. Each cell is 90 answers: 30 claims, asked three times.
Made-up DOIs at the lowest and highest effort level, September 2026
| Model | Lowest level | Highest level | Real change? |
|---|---|---|---|
| Claude Sonnet 5 | Low: 14.7% | Max: 3.4% | Yes, 1 in 500 |
| Gemini 3.7 Flash | Minimal: 13.3% | High: 4.5% | Yes, 1 in 60 |
| GPT-5.6 Luna | Minimal: 23.0% | Xhigh: 17.8% | No, 1 in 3 |
| Claude Opus 5.5 | Low: 0.0% | Max: 0.0% | Nothing to cut |
Made up means the DOI exists in neither Crossref nor DataCite, the two registries that issue DOIs. The last column is how often a gap that big would show up between two identical settings. We call a change real when that is rarer than 1 in 20. The claims and the scoring are the same as in our first citation test.
Each lab names its levels its own way. High on Gemini is not high on GPT. Compare levels within one model, never across two.
Where more effort helped: Sonnet 5 and Gemini 3.7 Flash
Sonnet 5 got better with each step, from 14.7% of its DOIs made up at low to 9.1% at high and 3.4% at max. Its three runs at max came in between 2.4% and 5.1%. No run at low came in under 9.5%.
Gemini 3.7 Flash barely moved until the last step. It went from 13.3% at minimal to 11.9% at low and 10.9% at medium. Then high cut it to 4.5%, less than half the rate at medium.
Each model has its own page with the full results:
- Claude at three effort levels, with Sonnet 5 and Opus 5.5 and what each level cost.
- Gemini 3.7 Flash at four thinking levels, and why only the top level helped.
Where it did not help: GPT-5.6 Luna
GPT-5.6 Luna made up 23.0% of its DOIs at minimal effort. The rate fell to 14.1% at high, then rose to 17.8% at xhigh. No pair of levels was far enough apart for our test to call real.
GPT-5.6 Luna also changed how it handled invented claims. We made up half our claims, so the right answer to those is that no source backs them. At minimal and low, GPT-5.6 Luna said so every time: 0 of 90 answers offered a source. At medium and above, it offered sources for an invented claim in 5 of 135 answers.
Five cases could be chance. A gap that size would turn up about 1 time in 6 between two identical settings. Treat it as a lead worth testing again with more claims.
Two of those five answers pointed to a real paper on a nearby topic. A real paper on the wrong claim passes a quick click, because the link works. That is why we check what each source says, with four models from different labs, not only that it exists.
The run-by-run results are in GPT-5.6 Luna at five effort levels.
Opus 5.5 made up nothing at any level
Claude Opus 5.5 gave 466 DOIs across low, medium and max effort. Every one of them was real. It turned down every invented claim, at every level.
In 43 of its 135 answers to invented claims, it then named real papers on a related topic. Each time, it said they did not back the claim. We did not count that against it.
A clean score on 30 claims is not a promise about claim 31. The next claim may be the one it gets wrong. That is why we check each claim against four models from different labs instead of trusting one, however good it looks this week.
What the research says, and where we differ
Two papers lead the search results for this question. In September 2025, Zhao and colleagues tested reasoning models on knowledge-heavy tasks. More thinking time did not reliably raise accuracy, and it often led to more hallucinations.
They traced most of that to one thing: a model's willingness to answer. Longer reasoning made models try more questions, and many of the new answers were wrong.
Our GPT result points the same way. GPT-5.6 Luna began offering sources for invented claims only at medium effort and above. Five cases are too few to prove it.
Our main result differs from theirs. In our test, effort cut made-up citations by more than half for two of four models. Their tasks and ours were not the same. They asked knowledge-heavy questions, and we asked for sources, so both results can hold.
In May 2025, Yao and colleagues asked whether reasoning models hallucinate more. Their answer was that it depends on how the model was trained. Models that went through a full training pipeline mostly hallucinated less. Some trained by shortcuts hallucinated more.
We cannot see how any of our four models was trained, so we cannot test that. But the part about it depending on the model fits. The same setting moved four models four different ways.
More effort costs more, by very different amounts
A model at higher effort writes more before it answers, and you pay for that. Here is the cost per 100 answers at each model's lowest and highest level, at list price.
Cost per 100 answers, lowest and highest effort level
| Model | Lowest level | Highest level | Times as much |
|---|---|---|---|
| Claude Sonnet 5 | $0.20 | $4.64 | 23x |
| Claude Opus 5.5 | $1.01 | $8.80 | 8.7x |
| GPT-5.6 Luna | $0.06 | $0.48 | 8.5x |
| Gemini 3.7 Flash | $0.26 | $0.57 | 2.2x |
Within Claude, the cheapest clean setting was Opus 5.5 at low. It cost $1.01 per 100 answers and made up no DOIs. Sonnet 5 at max cost $4.64 and still made up 3.4%.
Max effort can also fail in its own way. Twice, Sonnet 5 at max spent its whole budget of 32,000 tokens (word pieces) on thinking. It returned nothing at all.
Which effort level to use for sources
This is for one job: asking a model to name sources for a claim, from memory. Coding and agent work are different tasks, and effort may pay off there in other ways.
Effort level for listing sources, by model
| Model | Use | Why |
|---|---|---|
| Claude Sonnet 5 | Max, or Opus 5.5 at low | 3.4% at max against 14.7% at low. Opus 5.5 at low made up none and cost less. |
| Claude Opus 5.5 | Low | 0% at every level, so the cheapest level is the best buy. |
| Gemini 3.7 Flash | High | 4.5%, against 10.9% to 13.3% at the other three levels. |
| GPT-5.6 Luna | Minimal or low | No level beat them by a margin we could confirm, and they never backed an invented claim. |
Turning effort up is not a fact-check. At their best level, three of the four models still made up about one DOI in 30 or worse. Check every source before you publish it.
Every model at every level
These are the numbers behind the chart at the top of this post. Each row is 90 answers: 30 claims, asked three times at one level.
Made-up DOIs by model and effort level, 30 claims, three runs, September 2026
| Model and level | DOIs given | Made up | Rate | 95% range | Cost per 100 answers |
|---|---|---|---|---|---|
| Sonnet 5, low | 129 | 19 | 14.7% | 9.6 to 21.9% | $0.20 |
| Sonnet 5, high | 121 | 11 | 9.1% | 5.2 to 15.5% | $0.52 |
| Sonnet 5, max | 119 | 4 | 3.4% | 1.3 to 8.3% | $4.64 |
| Opus 5.5, low | 153 | 0 | 0.0% | 0.0 to 2.4% | $1.01 |
| Opus 5.5, medium | 160 | 0 | 0.0% | 0.0 to 2.3% | $1.24 |
| Opus 5.5, max | 153 | 0 | 0.0% | 0.0 to 2.4% | $8.80 |
| GPT-5.6 Luna, minimal | 126 | 29 | 23.0% | 16.5 to 31.1% | $0.06 |
| GPT-5.6 Luna, low | 126 | 26 | 20.6% | 14.5 to 28.5% | $0.06 |
| GPT-5.6 Luna, medium | 133 | 23 | 17.3% | 11.8 to 24.6% | $0.10 |
| GPT-5.6 Luna, high | 128 | 18 | 14.1% | 9.1 to 21.1% | $0.28 |
| GPT-5.6 Luna, xhigh | 129 | 23 | 17.8% | 12.2 to 25.3% | $0.48 |
| Gemini 3.7 Flash, minimal | 135 | 18 | 13.3% | 8.6 to 20.1% | $0.26 |
| Gemini 3.7 Flash, low | 135 | 16 | 11.9% | 7.4 to 18.4% | $0.24 |
| Gemini 3.7 Flash, medium | 137 | 15 | 10.9% | 6.7 to 17.3% | $0.40 |
| Gemini 3.7 Flash, high | 133 | 6 | 4.5% | 2.1 to 9.5% | $0.57 |
The 95% range is where the true rate likely sits, given how many DOIs we saw. Cost is what we paid per 100 answers at list price.
How we ran it
We used the same 30 claims as our earlier citation tests, word for word. Half have real research behind them. We made up the other half, so no real paper backs them. For each claim we asked for up to three peer-reviewed sources, with a DOI for each. No model had web search, so every source came from memory.
The only thing we changed was the effort setting. Each model ran at three to five levels, three times each. That is 1,350 answers and 2,017 DOIs, run on 26 September 2026. Every answer had room for 32,000 tokens, so we never cut a model off.
A script then looked up every DOI in Crossref and DataCite. No AI model graded anything. For the invented claims, we also read by hand every answer that offered a source.
Thirty claims is a small test, so treat these rates as a direction, not a ranking. It covers one task. Effort levels mean different things on different models, so compare levels within one model, never across two.
FAQ
Does reasoning effort reduce hallucinations?
It depends on the model. In our September 2026 test of 1,350 answers, more effort cut Claude Sonnet 5's rate from 14.7% to 3.4%. It cut Gemini 3.7 Flash's from 13.3% to 4.5%. GPT-5.6 Luna showed no change we could confirm, and Claude Opus 5.5 made up none at any level.
Do reasoning models hallucinate more?
Not as a rule. A May 2025 study found it depends on how the model was trained. In our September 2026 test, higher effort cut made-up citations for two of four models. It left the other two with no change we could confirm.
Can more thinking make an AI answer questions it should refuse?
It may, going by our September 2026 test. At minimal and low effort, GPT-5.6 Luna offered no source for any of our invented claims. At medium and above, it did so in 5 of 135 answers. That fits a September 2025 study that found longer reasoning makes models try more questions. Five cases could still be chance.
Is max reasoning effort worth the cost?
Only for some models. In our September 2026 test, max cut Sonnet 5's made-up DOIs from 14.7% to 3.4%, at about 23 times the cost of low. For Opus 5.5 it bought nothing, since it made up none at any level. For GPT-5.6 Luna, xhigh cost about 8.5 times minimal with no gain we could confirm.
Can you compare high effort across Claude, GPT and Gemini?
No. Each lab sets its own levels, and high on one model is not the same amount of thinking as high on another. Compare levels within one model only.
Keep reading
Is There a Most Accurate AI Model?
The honest answer is no. The ranking changes with the task, the benchmark, and the month, and even the leader still hallucinates.
We Benchmarked the Models Behind Our Own Product
Six jobs in our product each pick an AI model. Exactly one of those choices had ever been tested. We built a deterministic benchmark. It ran 227 graded calls against a slate of four to five candidates. We changed five of the six. Two of the tables decided nothing. One of our own test labels turned out to be wrong. And the exercise found three bugs it was not looking for.
Every AI Tier List Measures the Same Six Things. Truth Isn't One.
A developer who built a $200k business on AI ranked 11 companies and 17 models across six categories. It is a good ranking. But in 27 minutes the words hallucination, accurate and sycophancy never come up. And one model gets marked down, in so many words, for checking its work. So we ran the missing column ourselves: nine models, both failure modes, three times each. It separates, and it does not agree with any capability ranking.
The Same Model Fabricated at 10.9% and 30.9%
Take one generation of models: published hallucination rates for it run from under 2 percent to over 60. The standard explanation is that different labs test different things, and that is true. Almost nobody has tested it directly, so we did. One model, one prompt, one scorer, three runs a side, and only the questions changed.
GPTZero's Hallucination Detector, Explained
It catches citations that don't exist. By GPTZero's own admission, it does not check whether what you wrote is true. Here is exactly what its hallucination and source tools do. Here is where the gap is, and what closes it.
Effort helped two models, and neither reached zero
Only one of four models made up no DOIs, and a clean score on 30 claims says little about claim 31. Paste your draft into TrueStandard. Four models from different labs check each claim and flag what none of them can back up, in about 60 seconds. Even at max effort, Sonnet 5 made up about one DOI in 30.
Check Your Draft →