Claude Opus 5.5 hallucination rate, measured
Does Claude Opus 5.5 fabricate fewer citations than Opus 5?
Claude Opus 5.5 invented none of the 154 DOIs it offered on 29 September, and Opus 5 invented 7 of 135, or 5.2 percent (p = 0.0045). A DOI is the permanent ID that links a citation to its paper, so an invented one points at nothing. On 23 October Opus 5.5 again invented none, this time of 153. Opus 5 fell to 1.4 percent, and chance alone would open that gap about 22 times in 100 (p = 0.22). Count real IDs pinned to the wrong paper too, and Opus 5.5 got fewer wrong on both days: p = 0.0004, then 0.011. On either day, its true rate could still be as high as 2.4 percent.
Read this if you draft with Claude Opus 5.5 and publish the sources it gives you.
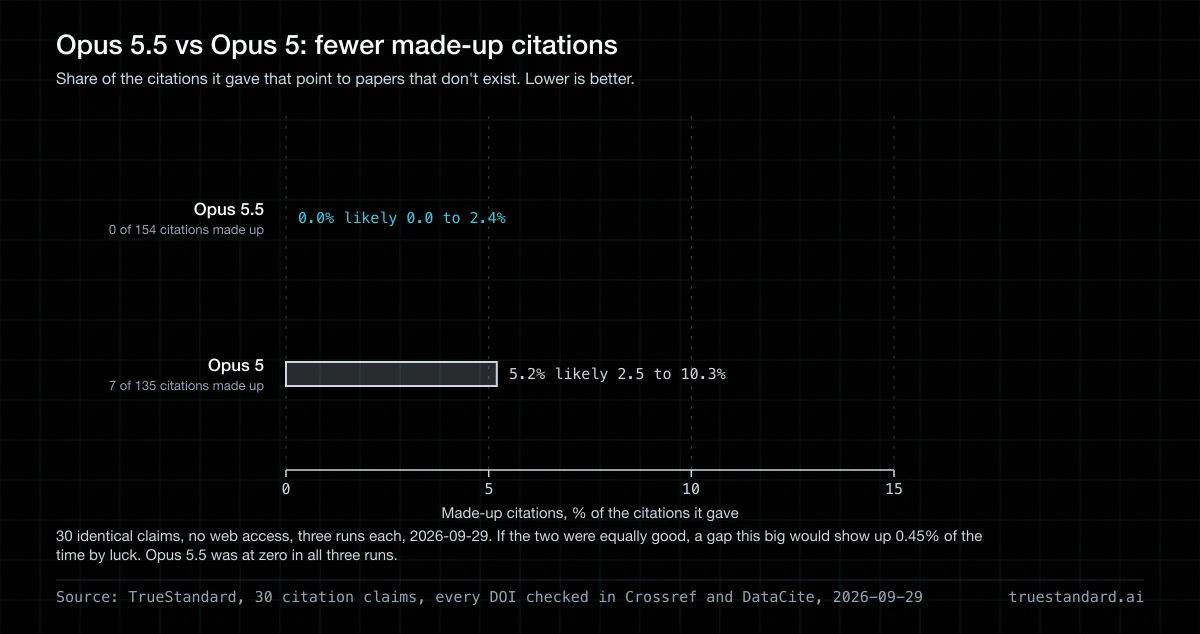
Zero in every run, on two days
On 29 September, Opus 5.5 invented 0 percent of its DOIs in all three runs. Opus 5 ran the same thirty claims on the same day and invented 2.2 percent, then 6.7, then 6.7.
Pooled, that is 0 of 154 against 7 of 135. A Fisher exact test, which asks how often chance alone would open a gap this size, gives p = 0.0045. No single run clears that bar alone, but all three point the same way. Add the citations that point at a real paper the model did not describe, and the gap widens. Opus 5.5 made none of those either. Opus 5 made three, which puts the pair at 0 percent wrong against 7.4 (p = 0.0004). On 23 October we ran all three models again. Opus 5.5 invented none of its 153 DOIs and miscited none. Opus 5 invented 0 percent, then 2.2, then 2.2, so it made 2 fakes in 138, or 1.4 percent (0.4 to 5.1). That gap gives p = 0.22, short of the bar. Opus 5 also miscited four real IDs. Counting both kinds, the pair sat at 0 percent wrong against 4.3 (p = 0.011), so the combined gap is the one both days support.
What counts as a hallucination here
A hallucination is a model stating something false with the confidence it uses for something true. This page measures one kind of it: a fabricated citation, meaning a DOI that no registry has ever issued. We measure that kind because it has an objective answer. Whether a claim is true can be argued. Whether a DOI resolves cannot. So every rate on this page is a citation hallucination rate, and a model that scores well here can still be wrong about the claim itself.
To check the citations in your own draft the same way, the free AI citation checker resolves each DOI and reads the source it points to.
What we measured
Thirty claims, no internet access, the same prompt and settings, run three times on 29 September 2026. Opus 5.5 is the subject. Opus 5 is the model it replaces, measured here on the same day. Grok 4.3 is a control that has run in every test since the second one. It sits in another line and is never compared with the pair. It scored 7.6 percent here, at the low edge of its band, with an interval that overlaps its last reading. Three more runs on 23 October are in the note below the table.
Made-up DOIs from Claude Opus 5.5 and the models beside it. Three runs of the same 30 claims on September 29, 2026.
| Model | Role | Run 1One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run. | Run 2 | Run 3 | Run spreadThe lowest run and the highest run. A wide spread tells you that one run alone can give a different answer. | All runsThe made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model. | Likely rangeThe span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart. |
|---|---|---|---|---|---|---|---|
| Opus 5.5 | subject | 0.0% | 0.0% | 0.0% | 0.0–0.0% | 0.0% | 0.0–2.4% |
| Opus 5 | predecessor | 2.2% | 6.7% | 6.7% | 2.2–6.7% | 5.2% | 2.5–10.3% |
| Grok 4.3 | control | 6.7% | 8.9% | 7.1% | 6.7–8.9% | 7.6% | 4.2–13.4% |
Each row shows one model. Run 1, Run 2 and Run 3 show the share of its DOIs that no registry knows. Run spread shows the lowest and the highest run. All runs adds the three runs together. Likely range shows where the true rate most likely sits, 95 times in 100.
How to read this
- Run
- One run puts all 30 claims to the model once. The prompt and the settings stay the same in each run.
- Run spread
- The lowest run and the highest run. A wide spread tells you that one run alone can give a different answer.
- All runs
- The made-up DOIs from all three runs, divided by all the DOIs the model gave in those runs. That is about 135 DOIs for each model.
- Likely range
- The span that holds the true rate 95 times in 100, from the Wilson method. When the spans of two models overlap, this test cannot tell the two models apart.
- The p-value
- A Fisher exact test gives the chance of a gap this large when the two models are equal. We treat a p-value above 0.05 as noise.
- Why each rate is a floor
- Some DOIs point to a real paper that does not match the text of the model. We do not count these DOIs as made up. So the true rate is equal to the rate here or higher.
The rate divides invented DOIs by DOIs offered. A DOI counts as invented only when no registry has issued it. Pooled over three runs, Opus 5.5 invented 0 of 154, with a 95 percent interval of 0 to 2.4 percent. Opus 5 invented 7 of 135, from 2.5 to 10.3 percent, and Grok 4.3 invented 10 of 132, from 4.2 to 13.4 percent. Fisher exact on the pair gives p = 0.0045, and run by run it gives 0.47, 0.096 and 0.099. Three of Opus 5's DOIs led to a real paper whose title did not match what it wrote. We graded each against the paper's registered first author and year, and all three were miscitations. Counting both kinds of error, Opus 5.5 got 0 of 154 wrong and Opus 5 got 10 of 135 (p = 0.0004). The whole test covered two release pages and cost $2.35. On 23 October 2026 we ran the same test three more times, and we compare the two days rather than pool them. Opus 5.5 invented 0 of 153, 0 to 2.4 percent. Opus 5 invented 2 of 138, 0.4 to 5.1 percent, and Grok 4.3 invented 18 of 129, 9.0 to 21.0 percent, the top of its band. Fisher exact on the pair gives p = 0.22, and run by run it gives 1.0, 0.47 and 0.48. Opus 5 had 4 miscitations and Opus 5.5 had none. Counting both kinds of error, Opus 5.5 got 0 of 153 wrong and Opus 5 got 6 of 138 (p = 0.011). The second day cost $2.21 for both pages. Its files are runs/run-v16-2026-10-23-r1.json and its two siblings, with the scored- and graded- files beside them.
What this data cannot tell you
- It cannot rank vendors. Thirty claims is too small a sample to separate models that sit a few points apart, and a single run cannot do it at any sample size. Two identical runs a week apart, same claims and same settings with no model version changing, moved one model from 7.0 to 13.3 percent and another from 4.7 to 0.0. Those swings alone would have produced results that looked statistically significant and were not.
- It only compares like with like. Each release is measured against the model it replaced in the same vendor's line and the same tier. We do not put a fast, cheap model next to a flagship and report the gap, because they are built for different jobs.
- It measures ungrounded recall, not the product you use. No web search, no retrieval, no tools. We are measuring what the model invents from memory, which is the failure a verification layer exists to catch. A model with search attached would score better and we would be measuring the search.
- A result that shows nothing still gets published. Most of these comparisons come back inconclusive, and we say so.
Opus 5.5 said no, then named real work
The thirty claims split into two groups. Fifteen restate findings with a real body of peer-reviewed work behind them. Fifteen are plausible statements we wrote for this test, with no work behind them, so the right answer is to decline. Opus 5.5 declined all fifteen in every run, 45 answers in all, and said so in its first sentence. In 13 of the 45 it then listed nearby real papers and said plainly that they did not support the claim. All 25 of those DOIs are real.
Those 25 count in its total of 154. On the real claims alone, it offered 129 DOIs and invented none. Opus 5 made all seven of its fakes on real claims. In the clearest cases it named a real paper with the right author and year, and only the ID was wrong. Some IDs were very close.
In run 3, Opus 5 cited Gazeau's 2007 paper on shellfish and carbon dioxide against 10.1029/2007GL028554. The real ID is 10.1029/2006GL028554, one digit away. Sonnet 5 cited the real one in this same test.
Opus 5 cited Murdoch's 2012 vitamin D trial twice, with two different IDs. Run 2 gave 10.1001/jama.2012.14172 and run 3 gave 10.1001/jama.2012.5307. Neither exists. Grok 4.3 cited the same trial as 10.1001/jama.2012.14185, which does not exist either.
We wrote this claim for the test, and no study backs it. Opus 5.5 said it knew of no such study, and that listing sources would mean inventing them. In run 1 it then named two real reviews that compare reading on paper and on screens. It said both measure comprehension and say nothing about oxytocin, so neither one supports the claim.
One trial, three fake IDs
Murdoch's 2012 vitamin D trial is real and well known. In this test it drew three different IDs from two models, and none of them exist. A reference with the right author, year and journal looks sound. When two models name the same paper, the paper is probably real. Whether its ID exists is a separate question, and a registry lookup is the only way to answer it.
Fabrication is one failure. Sycophancy is the other.
This benchmark measures fabrication: the model inventing a source it does not have. It does not measure sycophancy, the model bending its answer toward the opinion you showed it. A sycophantic model asked whether its own citation is real tends to say yes, which is why a model cannot be the check on its own draft. We test for both, with different instruments. Citations go to the registries that issue DOIs, the same check the hallucination checker runs on a pasted draft. Drafts go through the sycophancy detector, which scores how far a piece over-claims. If the word is new to you, what AI sycophancy is covers the mechanism.
Opus 5.5 made no errors on our thirty claims, and its true rate could still be as high as 2.4 percent. Your draft is not our thirty claims. The model it replaced looked careful too, and one of its fakes was a single digit off a real ID, a slip no reader will see. TrueStandard checks each claim and citation across four models from different labs, and against the registries that issue DOIs.
How current this is
Anthropic released Claude Opus 5.5 on 22 September 2026. This page went up on 29 September, seven days later, against the 48-hour target we set ourselves. We did test Opus 5.5 on 26 September, in our reasoning-effort test, but Opus 5 was not in that test. So it could not answer the question this page asks. Grok 4.7, the release before this one, took one day.
How we ran it
Every model gets the same thirty claims, the same prompt, the same settings, and no access to the internet. Fifteen claims are well documented and have real literature behind them. Fifteen are specific, plausible-sounding statements we constructed and know of no support for, which is where the pressure to invent a source comes from. We ask for up to three peer-reviewed sources with DOIs, then check every DOI against Crossref and, when Crossref does not hold it, DataCite. A DOI that exists in neither is counted as fabricated. A DOI that exists but resolves to a paper whose title does not match what the model described goes to a manual-review queue and is not counted on either side, so every rate here is a floor.
Three caveats. First, a model's rate moves between days, so we ran the pair again on 23 October, 24 days after the first. Opus 5.5 stayed at zero. Opus 5 fell from 5.2 percent to 1.4, a move chance could explain (p = 0.10). That pulled the invented-ID gap under the bar (p = 0.22), and the combined gap held (p = 0.011). Opus 5.5 also has a third clean day. On 26 September, at the same effort setting and on the same claims, it invented 0 of 153 DOIs. That test gave it more room to write, 32,000 tokens, or word pieces, against 3,000. No answer here came near the smaller limit, so the limit did not shape the result. Second, a zero on 153 or 154 DOIs has a 95 percent upper bound of 2.4 percent, and thirty claims is a small set. Third, both models ran at low reasoning effort with no web access. That is the setting most chat users get. Our separate effort test covers Opus 5.5 at higher settings. Our scorer checks DOIs against Crossref and DataCite. We then checked every dead ID at doi.org, which covers every agency: 35 from the first day and 32 from the second. None of them resolve.
The claim set, the prompt, the model identifiers, every raw response and every DOI verdict are committed beside the code that built this page, and a public mirror under CC BY 4.0 is being set up. Until it is live, ask and we will send the run files.
Related reading
Does Claude Hallucinate Less at Higher Effort?
Which Is the Best Claude Model? Fable, Opus, Sonnet, Haiku
Claude Fable 5.1 Review: The First Week
ChatGPT vs Claude vs Gemini: Which Is Most Accurate?
Claude Hallucination Rate by Version
Which AI hallucinates the least?
Common questions
Does Claude Opus 5.5 hallucinate citations?
It invented none on this test. With no web access, it offered 154 DOIs across three runs on 29 September and 153 on 23 October, and every one was real. A separate test on 26 September found 0 of 153. On either day, its true rate could still be as high as 2.4 percent.
Is Claude Opus 5.5 better than Opus 5 at citations?
On this test, it got fewer wrong on both days. Counting invented IDs and real ones pinned to the wrong paper, it was 0 percent against 7.4 for Opus 5 on 29 September (p = 0.0004), then 0 against 4.3 on 23 October (p = 0.011). Invented IDs alone cleared the bar only on the first day: p = 0.0045, then 0.22.
Why did Opus 5.5 give DOIs for claims you made up?
It first said it knew of no source and would not invent one. In 13 of 45 answers it then listed nearby real papers and said they did not support the claim. All 25 of those DOIs are real. On the real claims alone, it invented 0 of 129.
Why compare it to Opus 5 and not to Sonnet 5.5 or GPT?
Thirty claims cannot rank labs, and Sonnet is a different tier. We measure each release against the model it replaced, in the same line and tier. Sonnet 5.5 has its own page.
Why do other benchmarks give Opus 5.5 a high hallucination rate?
Because they measure something else. Most hallucination scores count wrong answers to hard questions. Ours counts citation IDs that no registry has issued. A DOI either resolves or it does not, so anyone can check our number without trusting a model to grade it.
Does Opus 5.5 cost more than Opus 5?
On this test, yes, even though its list price is 20 percent lower. It spent more tokens reasoning before it answered, and its refusals came with nearby papers attached. Across three runs it cost $0.93, against $0.68 for Opus 5.
Can I reproduce this?
Yes. We keep every input and output: the claims, the prompt, the model IDs, all three runs of raw answers, every DOI verdict and the graded miscitation file. The first day cost $2.35 and the second $2.21, each covering this page and the Sonnet 5.5 page. Ask and we will send the run files.
Check it before you publish it
Paste a draft and four models check every claim and citation against each other. You see where they disagree, which is where the errors are.
The claim checker is free. Pro is $20 a month for 250 drafts, Max $40 for 500, and Ultra $200 for 3,000.