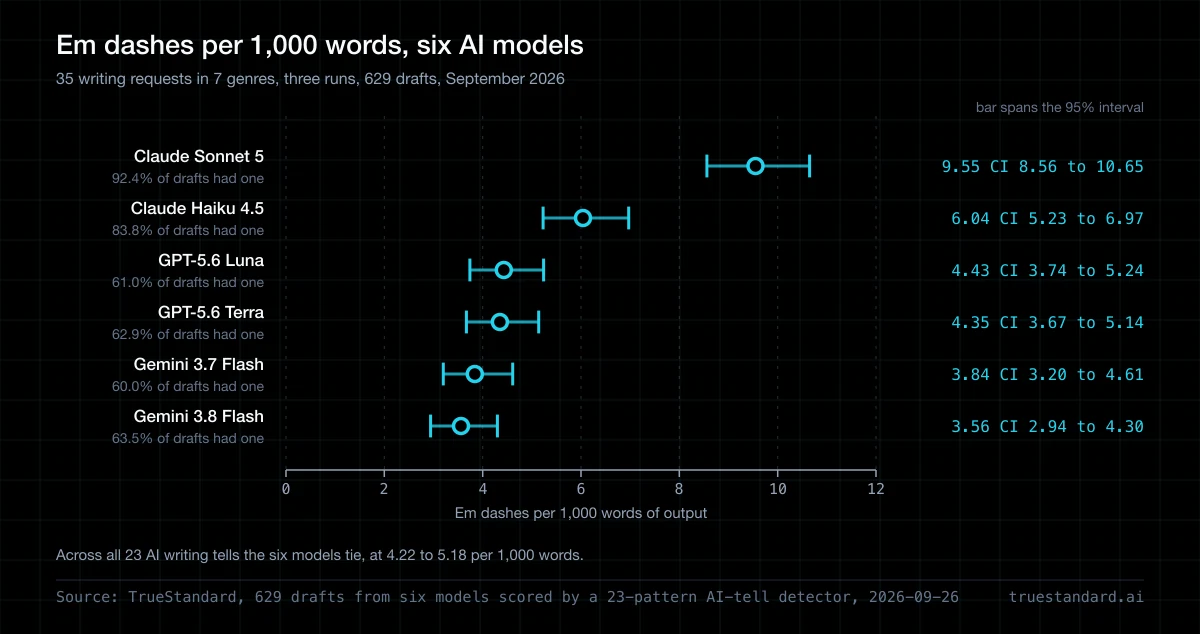
Claude Sonnet 5 used the most em dashes of the six AI models we tested: 9.55 per 1,000 words, or about three in a 300-word draft. That is more than twice the rate of GPT-5.6 and Gemini, which used 3.6 to 4.4. Claude Haiku 4.5 came second, at 6.04.
Every model used them. Between 60% and 92% of each model's drafts had at least one. But the em dash is one AI writing tell out of 23 we count. Across all 23, the six models land close together. What differs is which tell each one leaves.
Claude uses the most em dashes
We asked each model for 35 short pieces: blog posts, emails, product copy, opinion pieces, personal essays, LinkedIn posts and how-to guides. Each ran three times, so each row below is 105 drafts of about 300 words.
Em dashes per 1,000 words, six models, 629 drafts, September 2026
| Model | Em dashes per 1,000 words | 95% range | Lowest and highest run | Drafts with one or more |
|---|---|---|---|---|
| Claude Sonnet 5 | 9.55 | 8.56 to 10.65 | 9.14 to 10.03 | 92.4% |
| Claude Haiku 4.5 | 6.04 | 5.23 to 6.97 | 5.49 to 7.01 | 83.8% |
| GPT-5.6 Luna | 4.43 | 3.74 to 5.24 | 3.83 to 5.11 | 61.0% |
| GPT-5.6 Terra | 4.35 | 3.67 to 5.14 | 3.99 to 4.64 | 62.9% |
| Gemini 3.7 Flash | 3.84 | 3.20 to 4.61 | 2.83 to 4.67 | 60.0% |
| Gemini 3.8 Flash | 3.56 | 2.94 to 4.30 | 2.99 to 4.20 | 63.5% |
The 95% range is where the true rate likely sits. We also ran each model three times, and the run column shows its lowest and highest run. We only call one model higher than another when their runs do not overlap. Sonnet 5 clears all five others. Haiku 4.5 clears all four GPT and Gemini models. GPT and Gemini overlap each other.
Sonnet 5 went past two em dashes in 59.0% of its drafts. More than two in one draft is where our AI slop detector flags them. The GPT models did so in 16% to 19% of drafts, and the Gemini models in 9% to 11%.
You may have read that Claude stopped using em dashes. A public test on GitHub found 0.05 per 1,000 words for Claude Opus 5.5. That is a different model. We did not test Opus 5.5, so we cannot confirm it. Sonnet 5 and Haiku 4.5 still used more than any GPT or Gemini model we tested.
Across all 23 tells, the six models tie
Em dashes are one of 23 patterns our detector counts. The others include stock words like "seamless", lists of three, "studies show" with no study named, and endings that start with "Ultimately,". Counted across all 23, every model scored between 4.2 and 5.2 tells per 1,000 words.
All 23 tells per 1,000 words, same 629 drafts
| Model | Tells per 1,000 words | 95% range | Lowest and highest run |
|---|---|---|---|
| Claude Sonnet 5 | 5.18 | 4.46 to 6.01 | 4.57 to 5.69 |
| Gemini 3.7 Flash | 4.71 | 4.00 to 5.56 | 4.62 to 4.85 |
| Gemini 3.8 Flash | 4.57 | 3.86 to 5.40 | 3.99 to 5.29 |
| Claude Haiku 4.5 | 4.49 | 3.80 to 5.31 | 3.75 to 5.13 |
| GPT-5.6 Luna | 4.33 | 3.65 to 5.13 | 4.04 to 4.52 |
| GPT-5.6 Terra | 4.22 | 3.55 to 5.00 | 3.99 to 4.60 |
Every model's runs overlap at least one other model's, so none of them writes clearly more like AI than the rest. The four count rules score once per draft: too many em dashes, lists of three, "rather than" and "not Y" endings. Every other tell scores once per match.
So by count, no model writes most like AI. Which tell to look for depends on who wrote the draft.
Each vendor leaves a different tell
The totals tie because each vendor's models lean on a different habit. Claude leans on em dashes. GPT leans on lists of three. Gemini leans on stock AI words.
Share of drafts with each tell, by vendor, two models each
| Tell | Claude | GPT | Gemini |
|---|---|---|---|
| More than two em dashes | 42.4% | 17.6% | 10.0% |
| Too many lists of three | 56.7% | 86.2% | 70.3% |
| A stock AI word, like "seamless" | 17.1% | 5.7% | 23.9% |
| "Serves as" or "represents a" instead of "is" | 0.5% | 0.5% | 5.3% |
Each cell pools about 210 drafts: two models, 35 prompts, three runs. A draft of 300 words is allowed one list of three before it counts. Claude's lead on em dashes and GPT's lead on lists of three are far beyond chance. Gemini's lead on stock words is clear against GPT, but not against Claude.
Here is one line from each vendor, from the first run:
A concert or major sporting event in a city can spike demand—and prices—for flights there.
Claude Sonnet 5, a blog post on airline prices
Stay cool, hydrated, and prepared with a water bottle that works as hard as you do.
GPT-5.6 Terra, a product description
The logistics and supply chain landscape is evolving faster than ever.
Gemini 3.8 Flash, a LinkedIn post about a new job
LinkedIn posts carry the most tells
The kind of writing mattered more than the model. LinkedIn posts carried 7.20 tells per 1,000 words. Personal essays carried 1.87, about a quarter as many. Opinion pieces and product copy sat near LinkedIn.
Tells per 1,000 words by kind of writing, all six models pooled
| Kind of writing | Tells per 1,000 words | 95% range |
|---|---|---|
| LinkedIn post | 7.20 | 6.22 to 8.34 |
| Opinion piece | 6.56 | 5.67 to 7.58 |
| Product or marketing copy | 6.33 | 5.42 to 7.38 |
| Blog post | 3.99 | 3.31 to 4.80 |
| How-to guide | 3.34 | 2.72 to 4.09 |
| 3.08 | 2.46 to 3.85 | |
| Personal essay | 1.87 | 1.42 to 2.46 |
If you draft LinkedIn posts or sales copy with AI, expect about twice the tells of an email from the same model. The model reaches for the same moves a copywriter would: three benefits in a row, a punchy aside, a word like "seamless".
More thinking did not remove them
Some models let you set how long they think before they write. We ran two of them at more than one level. GPT-5.6 Luna ran at all five of its levels, from minimal to xhigh. Gemini 3.8 Flash ran at low and at high.
Neither changed. Luna's thinking grew about tenfold, from 26 to 245 tokens (word pieces) per draft, and its tells stayed between 3.8 and 4.3 per 1,000 words. Gemini 3.8 Flash went from no thinking to about 1,000 tokens, and its tells went from 4.57 to 5.15. That gap is small enough to be chance.
So a higher effort setting will not get you fewer tells, and it costs more.
Why AI uses em dashes
Nobody has shown why for certain. One idea, from engineer Sean Goedecke in October 2025, is that newer models learn from scanned print books from around 1900, which use more em dashes than writing today.
Our data cannot test that idea. It does show the habit is not fixed across AI. Six models got the same prompts and settings, and the heaviest user wrote 2.7 times as many as the lightest. That points to how each model was trained.
It also shifts when you ask. In November 2025, Tom's Guide reported that OpenAI's Sam Altman said ChatGPT now follows a custom instruction not to use them. We gave no such instruction, so these counts show each model's default.
An em dash does not prove AI wrote it
People used em dashes long before chatbots, and many still do. And the absence of one proves nothing either. About 38% of the GPT and Gemini drafts had no em dash at all, and they still came from AI.
A tell is a pattern. It proves nothing on its own. Our free AI slop detector runs the same 23 checks we used here and quotes each line it flags, so you can decide which ones to fix. The AI humanizer rewrites them for you.
A tell check cannot see whether a claim is true. A draft with no em dashes can still cite a study that does not exist. That is why TrueStandard checks the claims: paste your draft, and four models from different labs check each fact in about 60 seconds.
How we ran it
We wrote 35 plain requests, five each for seven kinds of writing. One was "Write an email to my landlord asking them to fix a leaking kitchen faucet." Each asked for about 300 words and the text only. We set no tone, no style and no system prompt.
Each model got every request three times, with the same settings: low reasoning effort and room for 32,000 tokens, or word pieces, so no draft was cut short. We ran them on 26 September 2026, through each vendor's API, so no chat app added its own instructions. One Gemini 3.8 Flash draft ended in an error and was dropped, leaving 629.
A script then scored every draft against the 23 patterns in our AI slop detector. It is plain pattern matching. No AI model graded anything.
We tested short first drafts from a bare request. A style guide or a custom instruction would change the counts. A flag is a pattern match. It is not a verdict: a how-to guide that says "12 to 24 hours" trips the vague-range check even when that range is right. We did not measure human writing, and we left out four flagship models for cost: Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra and Gemini 3.1 Pro.
FAQ
Which AI uses the most em dashes?
Claude, in our test. Claude Sonnet 5 used 9.55 em dashes per 1,000 words and Claude Haiku 4.5 used 6.04. GPT-5.6 Terra and Luna used about 4.4, and Gemini 3.7 and 3.8 Flash used 3.6 to 3.8. That is 629 drafts across seven kinds of writing, run in September 2026.
Why does AI use em dashes?
No one has proven why. One theory holds that newer models learned from old print books, which use more em dashes. Our test shows the habit varies a lot by model: on the same prompts, Claude Sonnet 5 used 2.7 times as many as Gemini 3.8 Flash. So it comes from how each model was trained.
Are em dashes a sign of AI writing?
They are a weak sign on their own. People use them too, and about 38% of the GPT and Gemini drafts in our test had none at all. Look for several tells together, such as em dashes, lists of three and words like "seamless", instead of any single one.
Does ChatGPT still use em dashes?
Yes, but less than Claude. With no instructions, GPT-5.6 Terra and Luna used about 4.4 em dashes per 1,000 words, and about 62% of their drafts had at least one. OpenAI says ChatGPT will follow a custom instruction not to use them.
What are the most common signs of AI writing?
In our 629 drafts, the most common was too many lists of three, in 71% of drafts. Next came too many em dashes, in 23%, and stock AI words like "seamless", "robust" and "landscape", in 16%. Which one you see most depends on the vendor.
Does higher reasoning effort make AI writing sound less like AI?
Not in our test. GPT-5.6 Luna at five effort levels and Gemini 3.8 Flash at low and high left the same number of tells, within the margin of chance, though thinking time grew about tenfold.
Keep reading
Multi-Agent vs Multi-Model AI in 2026
AI builders use both terms as if they meant the same thing. They are different architectures with different strengths. The difference matters most for the one job neither term sells: catching AI errors before you publish.
Long Context vs RAG in 2026
Three things just changed about how AI handles your documents. Here is what works for content teams, and why better retrieval still does not mean better truth.
AI Agent Workflow Patterns: When Each One Works (and When It Fails)
Six patterns cover almost every agent you'll build. Five are routine. The sixth, verification, breaks when you wire it with a single model, and most teams wire it that way.
Every Type of AI, Explained
From large language models to coding agents: what each type of AI does, which tools lead each group, and how to pick the right one for your work.
What Karpathy's AI Methods Don't Fix
In six weeks, Andrej Karpathy and AI builders shipped three viral reliability methods. Each is real and useful. None of them solves the checking problem for writers.
Fix the tells, then check the claims
You can strip every em dash and still publish a made-up statistic. Paste your draft into TrueStandard. Four models from different labs check each claim and flag what none of them can back up, in about 60 seconds.
Check Your Draft →