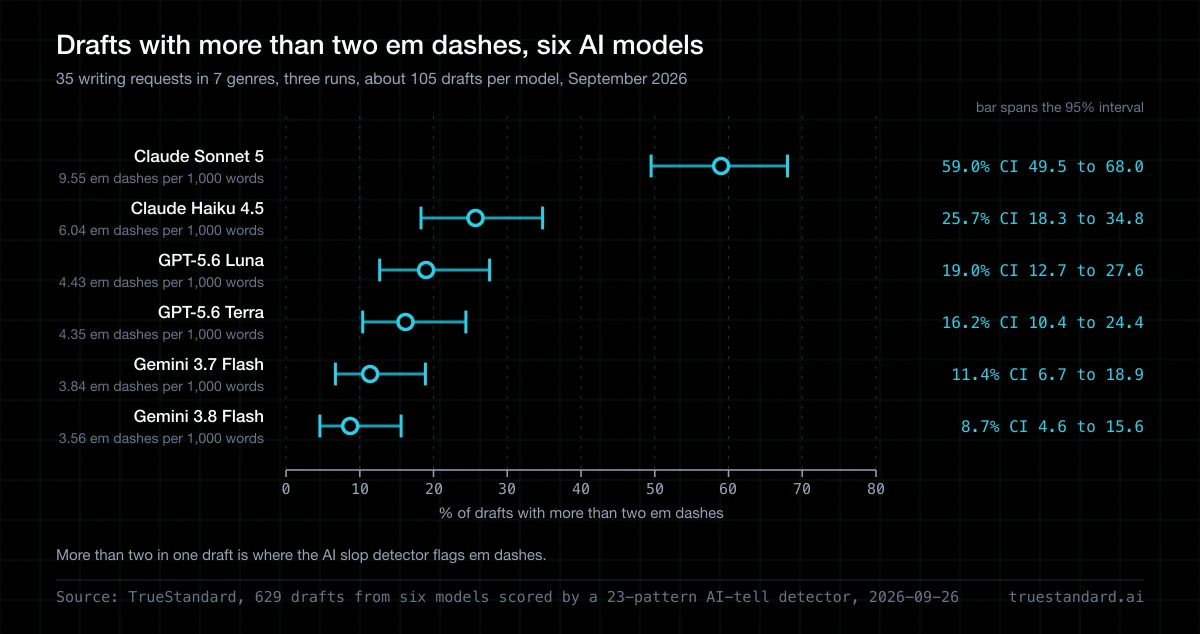
Yes, more than any other model we tested. Claude Sonnet 5 used 9.55 em dashes per 1,000 words, about three in a 300-word draft. Claude Haiku 4.5 used 6.04. GPT-5.6 and Gemini used 3.6 to 4.4 on the same jobs.
92% of Sonnet 5's drafts had at least one em dash, and 59% had more than two. On every other tell we count, Claude landed close to the other vendors. The em dash is Claude's habit.
Claude uses the most em dashes we measured
We asked each model for 35 short pieces in seven kinds of writing, from emails to LinkedIn posts. Each ran three times, so each row is 105 drafts of about 300 words. We called the models directly through Anthropic's API. The Claude app was not involved.
Em dashes per 1,000 words, Claude against GPT and Gemini, September 2026
| Model | Em dashes per 1,000 words | 95% range | Lowest and highest run | Drafts with more than two |
|---|---|---|---|---|
| Claude Sonnet 5 | 9.55 | 8.56 to 10.65 | 9.14 to 10.03 | 59.0% |
| Claude Haiku 4.5 | 6.04 | 5.23 to 6.97 | 5.49 to 7.01 | 25.7% |
| GPT-5.6 Luna | 4.43 | 3.74 to 5.24 | 3.83 to 5.11 | 19.0% |
| Gemini 3.7 Flash | 3.84 | 3.20 to 4.61 | 2.83 to 4.67 | 11.4% |
The 95% range is where the true rate likely sits. We call one model higher than another only when their three runs do not overlap. Sonnet 5's lowest run beat every other model's highest. Haiku 4.5's lowest run beat every GPT and Gemini model's highest. More than two in one draft is where our AI slop detector flags them.
Only 8 of Sonnet 5's 105 drafts had no em dash at all. One had eight. Here is one line from a blog post on airline prices:
A concert or major sporting event in a city can spike demand—and prices—for flights there.
Claude Sonnet 5, first run
Most of Sonnet 5's dashes stand alone, one to a sentence. Across its 105 drafts, 257 sentences had one, and 31 had a pair around an aside like the line above. Each reads fine on its own. Three to a draft is what a reader notices.
The Claude that dropped em dashes is Opus 5.5
You may have seen a chart showing Claude's em dashes falling to almost zero. One public test on GitHub measured Claude Opus 5.5 at 0.05 em dashes per 1,000 words, down from 12.9 for Opus 5.
That result is about Opus 5.5, which was outside this test's budget, so we cannot confirm it. On our prompts, Sonnet 5 and Haiku 4.5 still used more em dashes than any GPT or Gemini model.
The two tests also asked for different things. Theirs used its own prompts for long posts. Ours used short drafts across seven kinds of writing. So read the two numbers side by side. Do not read them as a trend.
Claude keeps them even in personal essays
Every vendor used more em dashes in opinion pieces and product copy than in emails. Claude differs in one place: personal essays. GPT used 2.18 per 1,000 words there, and Gemini 2.97. Claude used 8.14.
Em dashes per 1,000 words by kind of writing, Sonnet 5 and Haiku 4.5
| Kind of writing | Sonnet 5 | Haiku 4.5 |
|---|---|---|
| Opinion piece | 13.9 | 9.7 |
| Product or marketing copy | 13.2 | 6.5 |
| Blog post | 10.7 | 4.7 |
| LinkedIn post | 10.4 | 8.7 |
| Personal essay | 9.0 | 7.3 |
| How-to guide | 6.9 | 3.3 |
| 2.5 | 1.7 |
Each cell is 15 drafts: five requests, three runs. Small cells swing, so trust the order more than the second digit.
She laughed, not unkindly, and pressed her hands over mine, showing me the rhythm—push, fold, turn—until the dough became something smoother, something that could hold together.
Claude Sonnet 5, a personal essay about learning to cook, first run
In an essay, Claude uses the dash to hold a thought open, the way a writer might. So even Claude's most personal drafts carry the tell.
Its other tells are close to average
Across all 23 tells we count, Sonnet 5 scored 5.18 per 1,000 words and Haiku 4.5 scored 4.49. GPT and Gemini scored 4.22 to 4.71. The ranges overlap, so Claude does not write more like AI overall. It leans on a different tell.
Claude wrote the fewest lists of three: 7 to 8 per 1,000 words, against about 16 for GPT. It used stock AI words like "robust" and "meticulous" in 17.1% of drafts, between GPT's 5.7% and Gemini's 23.9%.
Haiku 4.5 had one habit of its own. It gave a range like "12-24 hours" or "2-3 weeks" in 11.4% of drafts, against 2.9% for Sonnet 5. Our detector flags a range because a writer who has done the thing can usually name one number. In a how-to guide the range may be right, so treat that flag as a prompt to check.
How to get fewer em dashes from Claude
Ask for none, in the prompt or in the instructions Claude keeps for you. We did not test how well it listens. Our counts show what Claude does when nobody asks.
To find the ones that slipped through, our free AI slop detector counts em dashes and 22 other tells, and quotes each line it flags. The AI humanizer rewrites them for you.
A style fix leaves the facts alone. A Claude draft with every dash removed can still name a study nobody ran. That is the part TrueStandard checks: paste your draft, and four models from different labs test each claim in about 60 seconds.
How we ran it
We wrote 35 plain requests, five each for seven kinds of writing. One was "Write a short personal essay about learning to cook from my grandmother." Each asked for about 300 words and the text only. We set no tone, no style and no system prompt.
Each model got every request three times, on 26 September 2026, through Anthropic's API with low reasoning effort. We gave every draft room for 32,000 tokens, or word pieces, so none was cut short. A script scored all 210 Claude drafts against the 23 patterns in our AI slop detector. No AI model graded anything.
This covers Claude Sonnet 5 and Claude Haiku 4.5 only. We left out Claude Opus 5.5 and Claude Fable 5.1 for cost. These are short first drafts from a bare request, and the Claude app adds its own instructions. A flag is a pattern match. It is not a verdict.
We ran the same test on GPT and Gemini. The six-model comparison has all of them side by side.
The other two vendors:
- GPT-5.6 Terra and Luna used under half Claude's em dashes, and the most lists of three.
FAQ
Does Claude use em dashes?
Yes. In our September 2026 test, Claude Sonnet 5 used 9.55 em dashes per 1,000 words, the most of six models, and Claude Haiku 4.5 used 6.04. GPT-5.6 and Gemini used 3.6 to 4.4 on the same 35 writing jobs.
Why does Claude use so many em dashes?
No one outside Anthropic knows for sure. On the same prompts and settings, Claude Sonnet 5 used about 2.7 times as many as Gemini 3.8 Flash, so the habit comes from how the model was trained. The task does not explain it.
Did Claude stop using em dashes?
Claude Opus 5.5 nearly did, in a public test that measured 0.05 per 1,000 words. We did not test Opus 5.5. Claude Sonnet 5 and Haiku 4.5 still used 9.55 and 6.04 per 1,000 words in our test.
How do I stop Claude from using em dashes?
Ask for none in your prompt or in Claude's saved instructions. We did not test how well it follows that. To catch the ones left, run the draft through a checker that counts them, like our free AI slop detector.
Does Claude use more em dashes than ChatGPT?
Yes, about twice as many. Claude Sonnet 5 used 9.55 per 1,000 words and GPT-5.6 Terra and Luna about 4.4, on the same 35 writing jobs, three runs each.
Keep reading
Multi-Agent vs Multi-Model AI in 2026
AI builders use both terms as if they meant the same thing. They are different architectures with different strengths. The difference matters most for the one job neither term sells: catching AI errors before you publish.
Long Context vs RAG in 2026
Three things just changed about how AI handles your documents. Here is what works for content teams, and why better retrieval still does not mean better truth.
AI Agent Workflow Patterns: When Each One Works (and When It Fails)
Six patterns cover almost every agent you'll build. Five are routine. The sixth, verification, breaks when you wire it with a single model, and most teams wire it that way.
Every Type of AI, Explained
From large language models to coding agents: what each type of AI does, which tools lead each group, and how to pick the right one for your work.
What Karpathy's AI Methods Don't Fix
In six weeks, Andrej Karpathy and AI builders shipped three viral reliability methods. Each is real and useful. None of them solves the checking problem for writers.
Check the claims in your Claude draft
Removing Claude's em dashes changes how a draft reads. It does nothing for whether the draft is right. Paste yours into TrueStandard. Four models from different labs check each claim and flag what none of them can back up, in about 60 seconds.
Check Your Draft →